Blog
No matches. Try another search.
Business · Jul 30, 2026
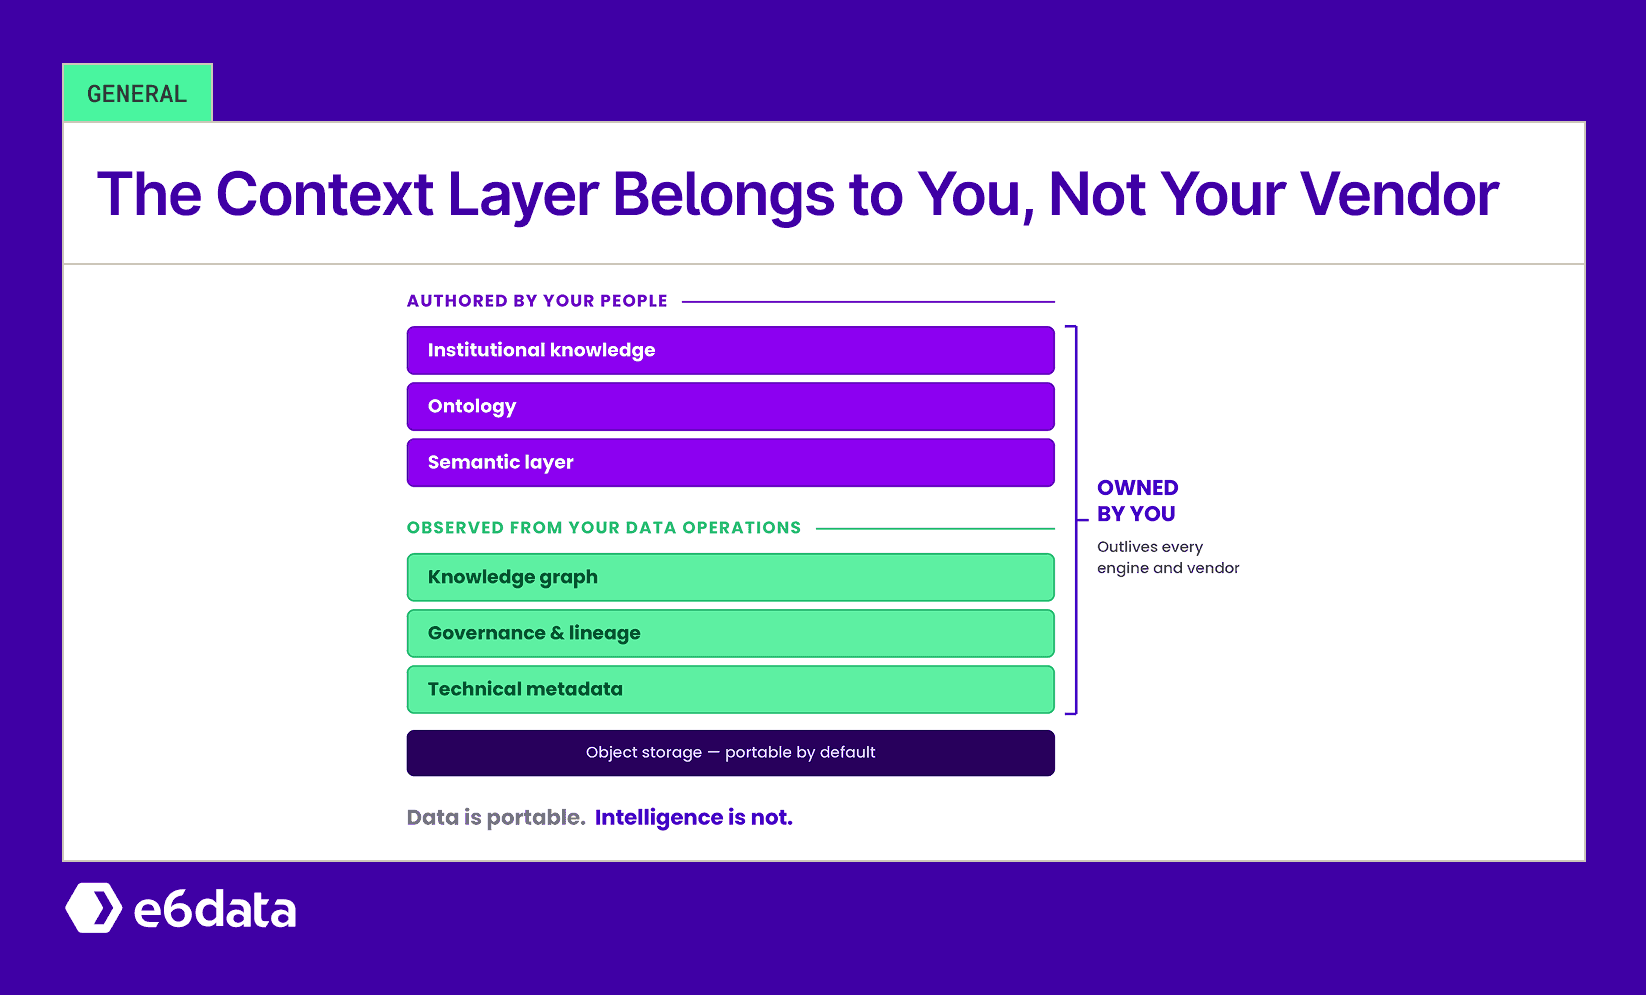
Why Enterprises Must Own the Context Layer for AI
This article explains why enterprises must own the context layer for AI that gives AI agents reliable business meaning. It shows how an enterprise context layer connects semantic metadata, governance, lineage, permissions, institutional knowledge, ontologies, and an enterprise knowledge graph. It also clarifies context layer vs semantic layer and semantic layer vs ontology, arguing that portable data does not guarantee portable intelligence or vendor-independent understanding. The recommendations reflect the article’s definition of a context layer as the connected business definitions, semantic metadata, relationships, lineage, permissions, freshness signals, and institutional knowledge needed to interpret enterprise data correctly. They also preserve its central argument: enterprises should retain control of this intelligence independently of individual tools, engines, and vendors.
Insights · Jun 26, 2026
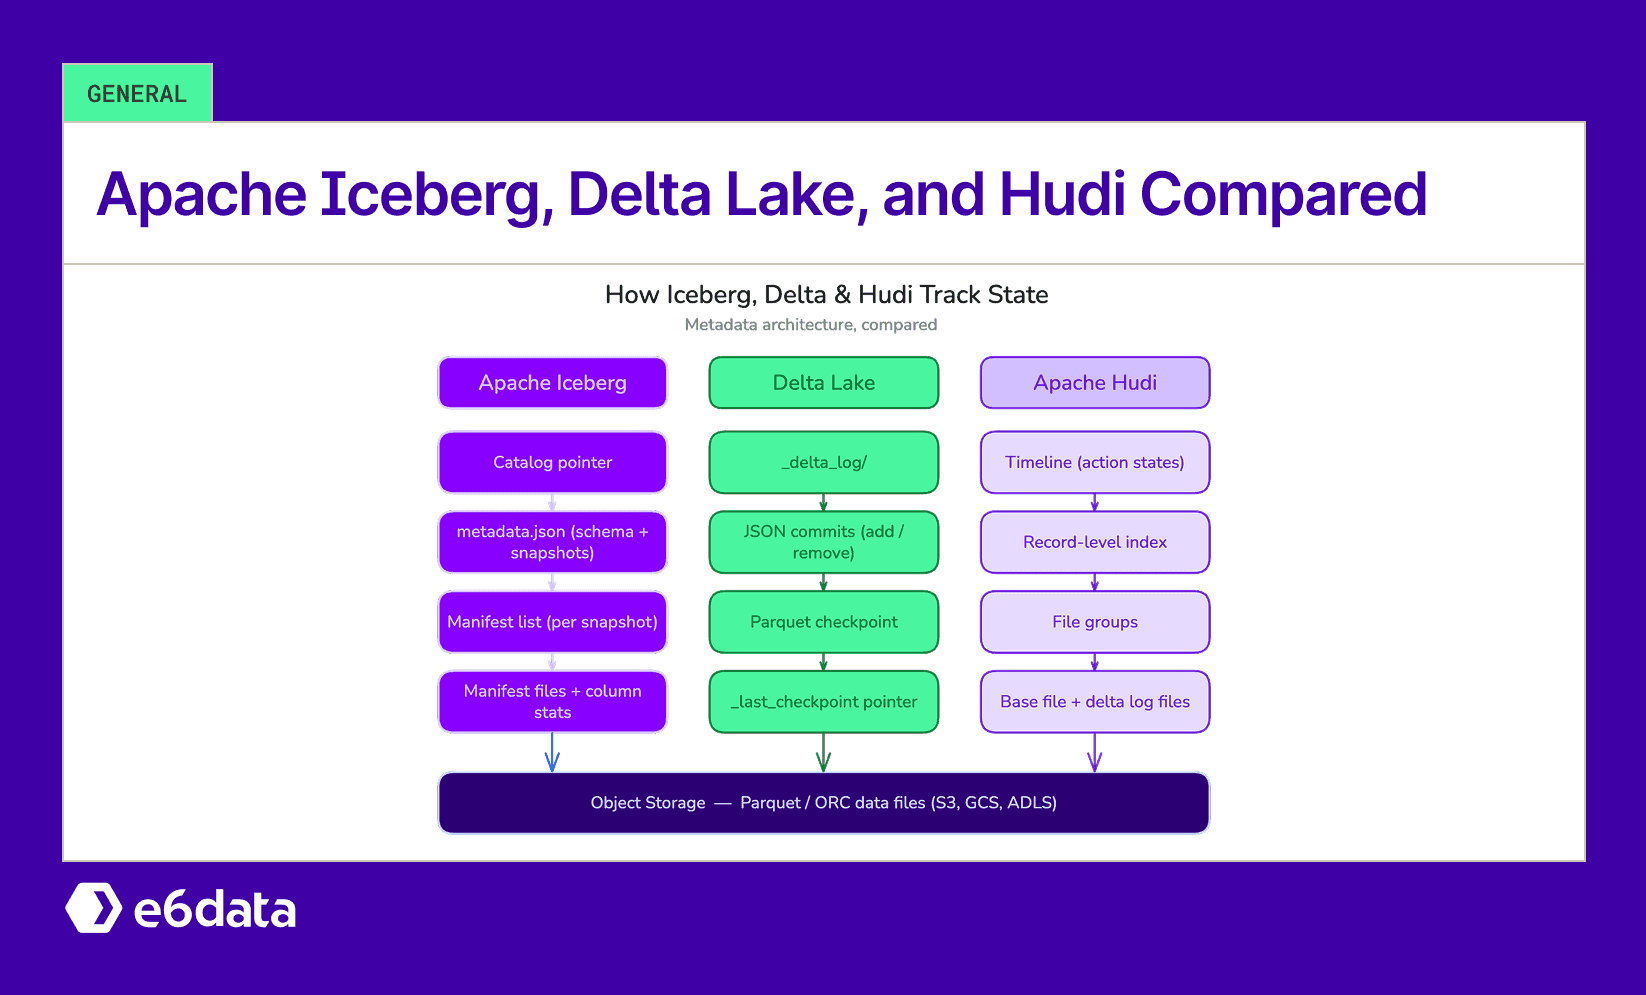
Apache Iceberg vs. Delta Lake vs. Hudi
Apache Iceberg, Delta Lake, and Apache Hudi solve similar lakehouse problems but suit different workloads. Iceberg is the strongest choice for open, multi-engine analytics; Delta Lake fits Databricks and Spark-centric environments; and Hudi is designed for streaming, CDC, and frequent upserts. This guide compares their metadata architectures, transaction models, concurrency, schema evolution, partitioning, and row-level mutations, while explaining how a format-agnostic engine can query all three without data movement or pipeline rewrites.
Company · Jun 11, 2026
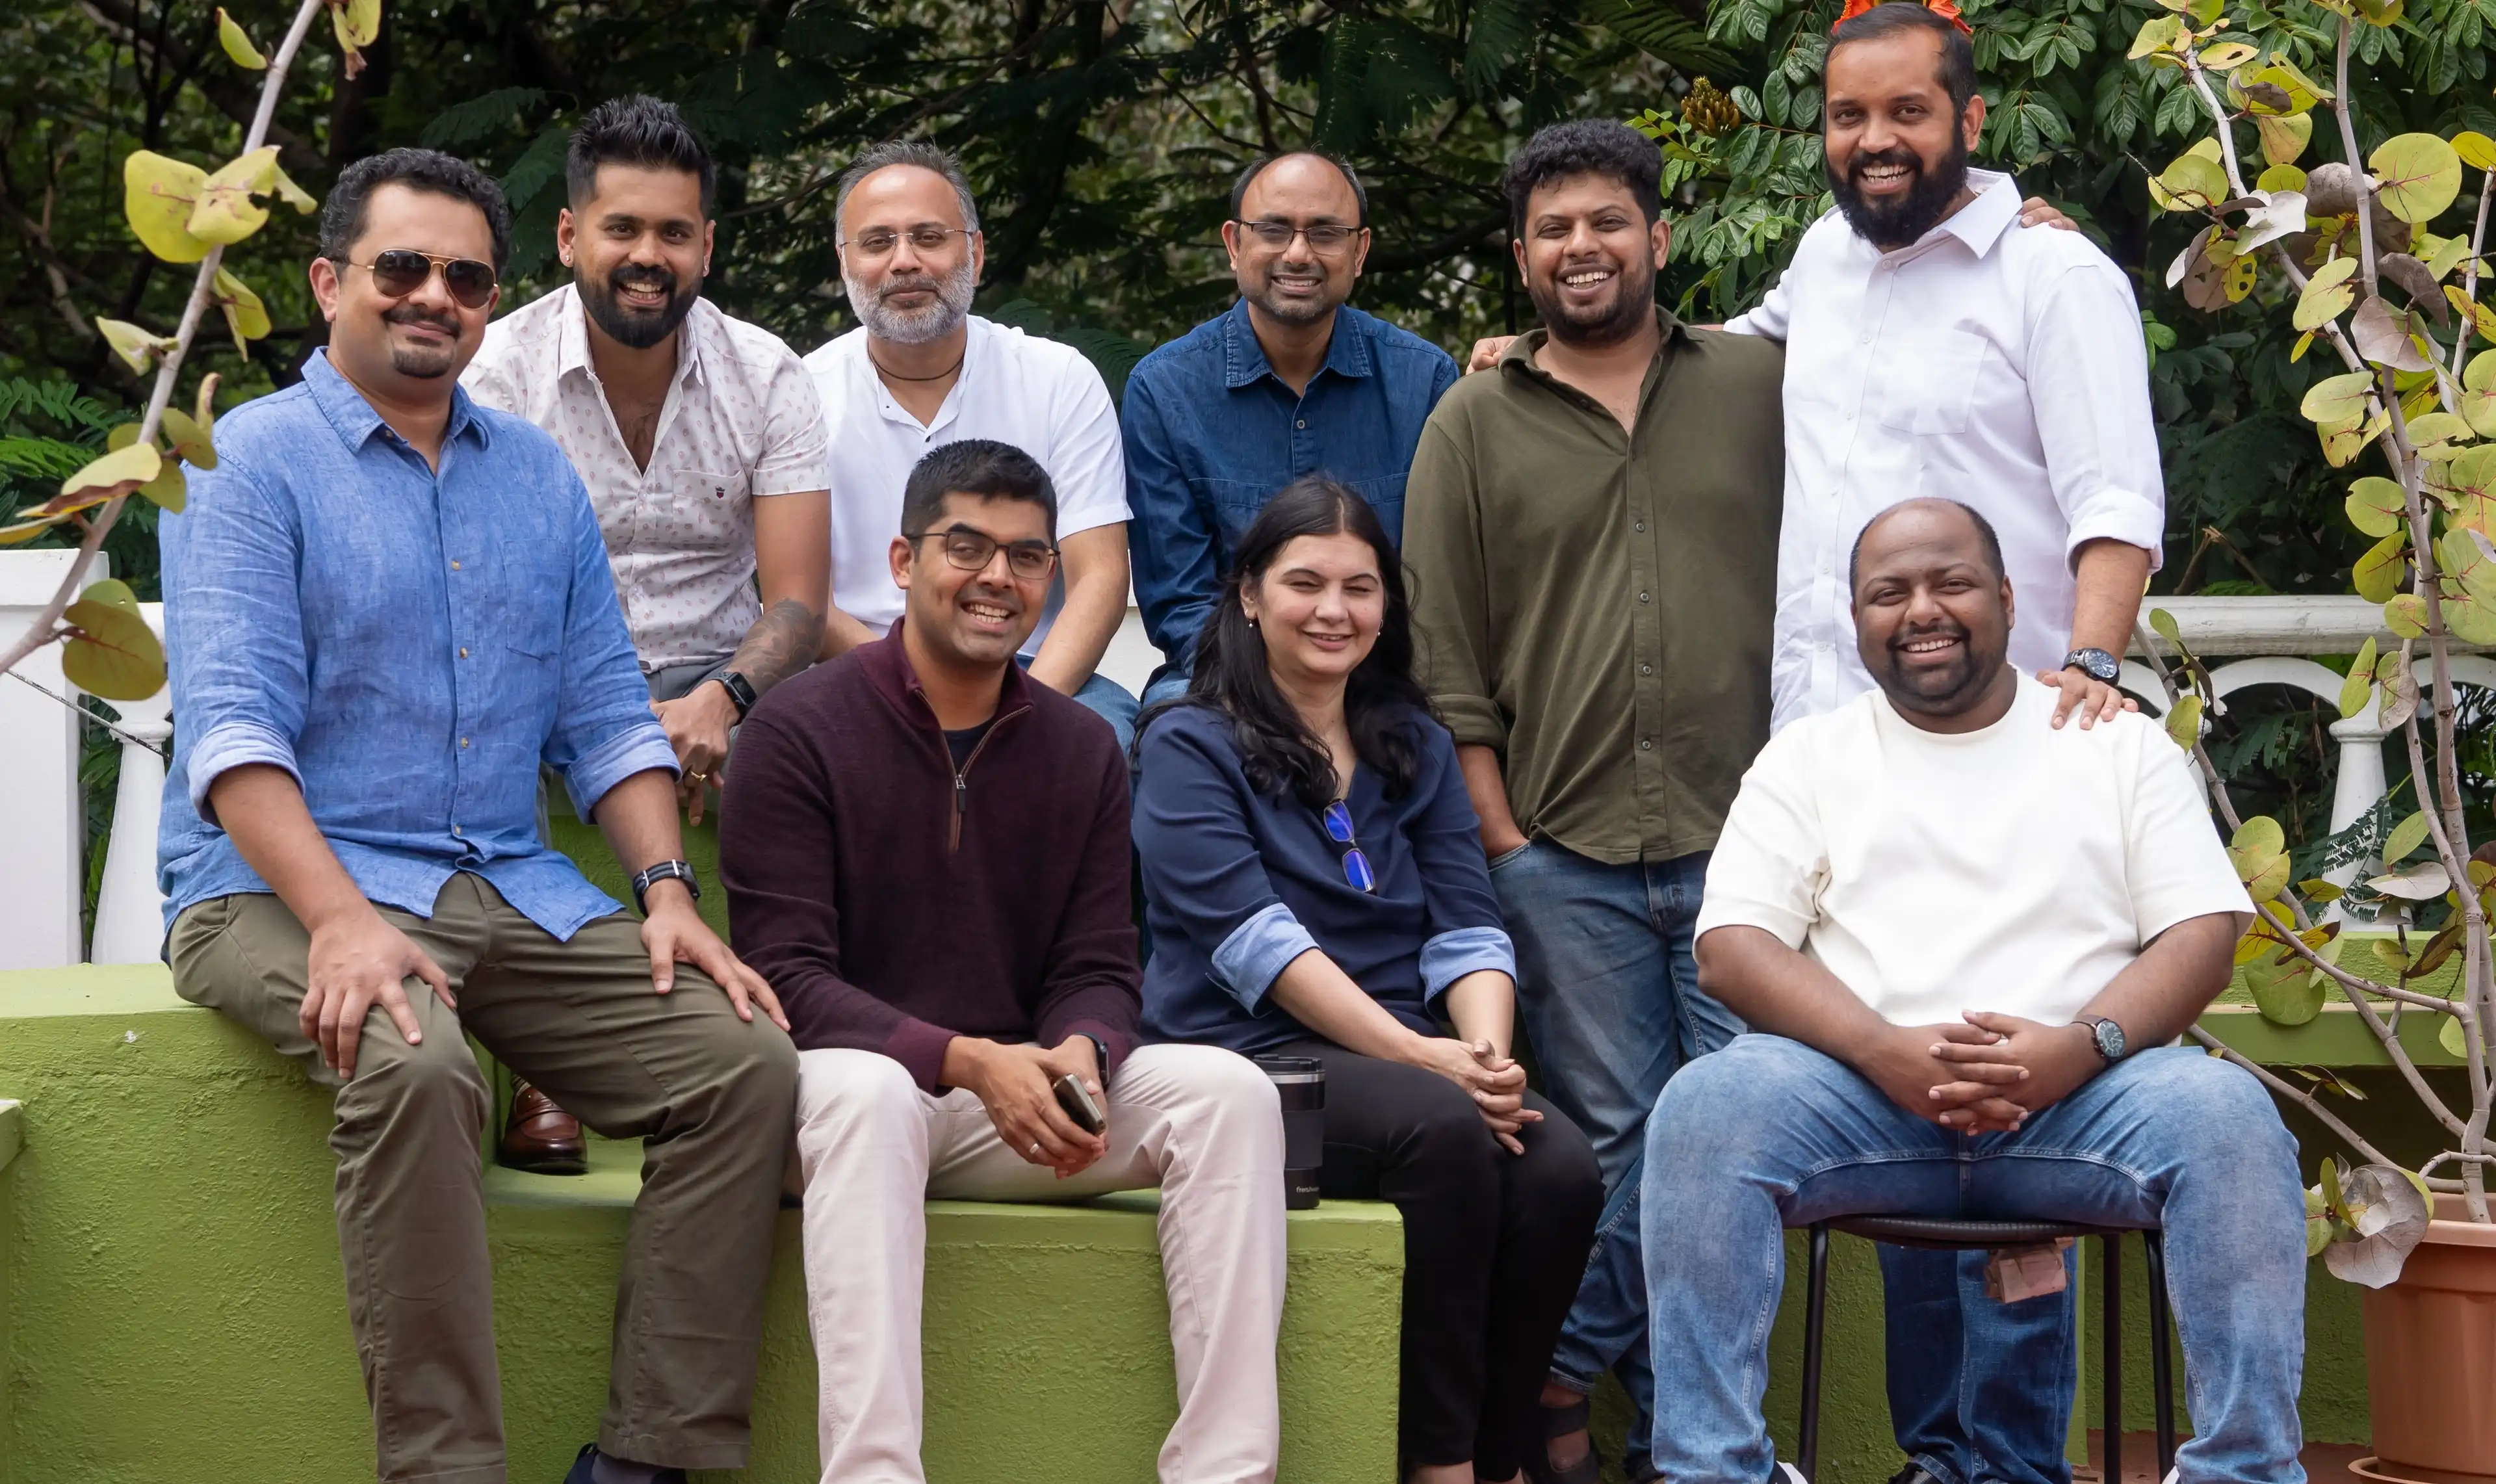
e6data raises $10m to dismantle lock-in from data intelligence vendors on analytics and AI by halving costs and increasing performance 5x
e6data to level the playing field for customers by negating the immense pricing power a handful of vendors enjoy due to various new forms of compute.
Engineering · May 22, 2026
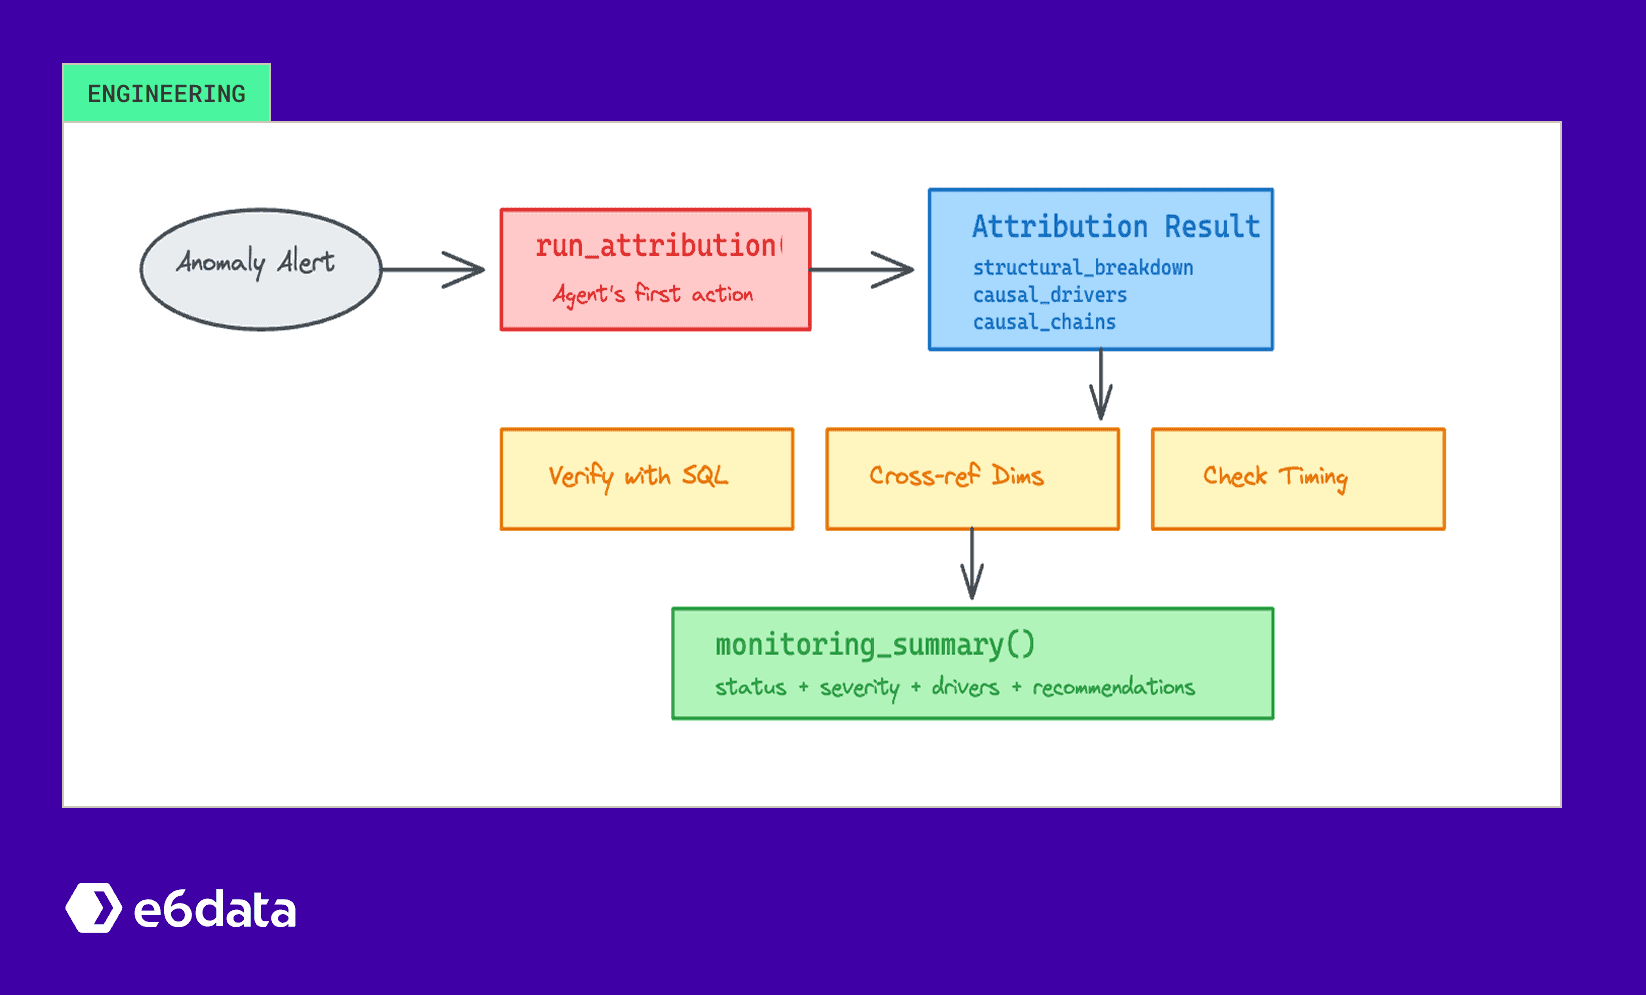
Building a Causal Attribution Engine for AI-Powered Root Cause Analysis
This blog shows how e6data decomposes metric anomalies into structural, causal, and narrative layers and feeds the output into an AI agent that can autonomously investigate incidents.
Insights · Apr 27, 2026
Decoupling the Data Stack: A Technical Guide to Apache Iceberg Query Engines
The structural shift from monolithic, proprietary data warehouses toward modular, open data lakehouse architectures is a financial and operational.
Insights · Apr 27, 2026
The 2026 Guide to Cloud Data Warehouse Tools
The transition to open table formats like Apache Iceberg and Delta Lake solved storage vendor lock-in. It also created a massive financial bottleneck at.
Insights · Apr 21, 2026
Embedded Analytics Tools for SaaS: Best Platforms for B2B SaaS Companies in 2026
This blog compares the top embedded analytics tools for B2B SaaS companies in 2026, covering platforms such as e6data, Looker, Tableau, Power BI, Sigma, ThoughtSpot, Sisense, GoodData, Qrvey, Metabase, Superset, and Mode. It explains what SaaS teams should evaluate when choosing an embedded analytics platform, including embedding flexibility, API-first architecture, multi-tenant support, row-level security, scalability, and white-label customization. The article positions e6data as the best fit for high-performance analytics on large datasets, while also outlining where other platforms are stronger, such as governance, visualization, search, open-source flexibility, or rapid deployment.
Business · Apr 21, 2026
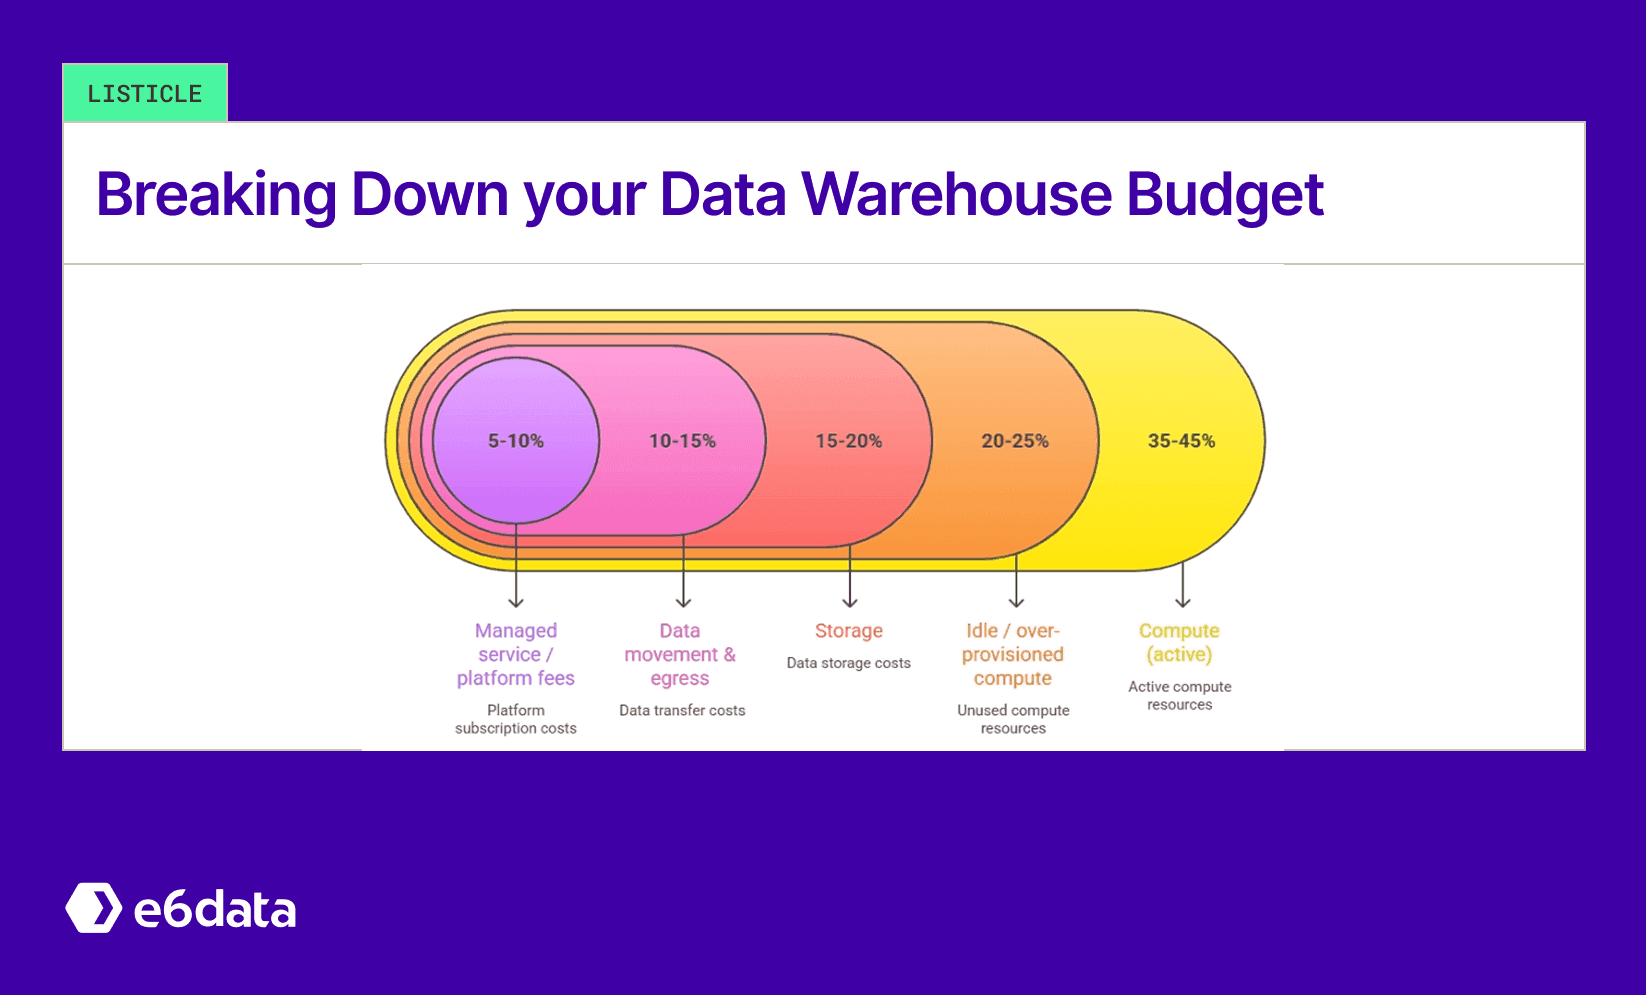
Data Warehouse Cost Optimization: A Complete Guide for Engineering and FinOps Teams
Learn proven data warehouse cost optimization strategies for Snowflake, BigQuery, Redshift, and more. This 2026 guide covers pricing models, cost drivers, step-by-step optimization tactics, and how e6data's Atomic Architecture delivers up to 60% lower compute costs without changing your architecture.
Engineering · Apr 13, 2026
Top Data Lakehouse Tools for Modern Analytics and AI Workloads
The shift from disparate data warehouses and data lakes to the lakehouse architecture is a structural response to the scaling limits of analytical.
Engineering · Mar 23, 2026
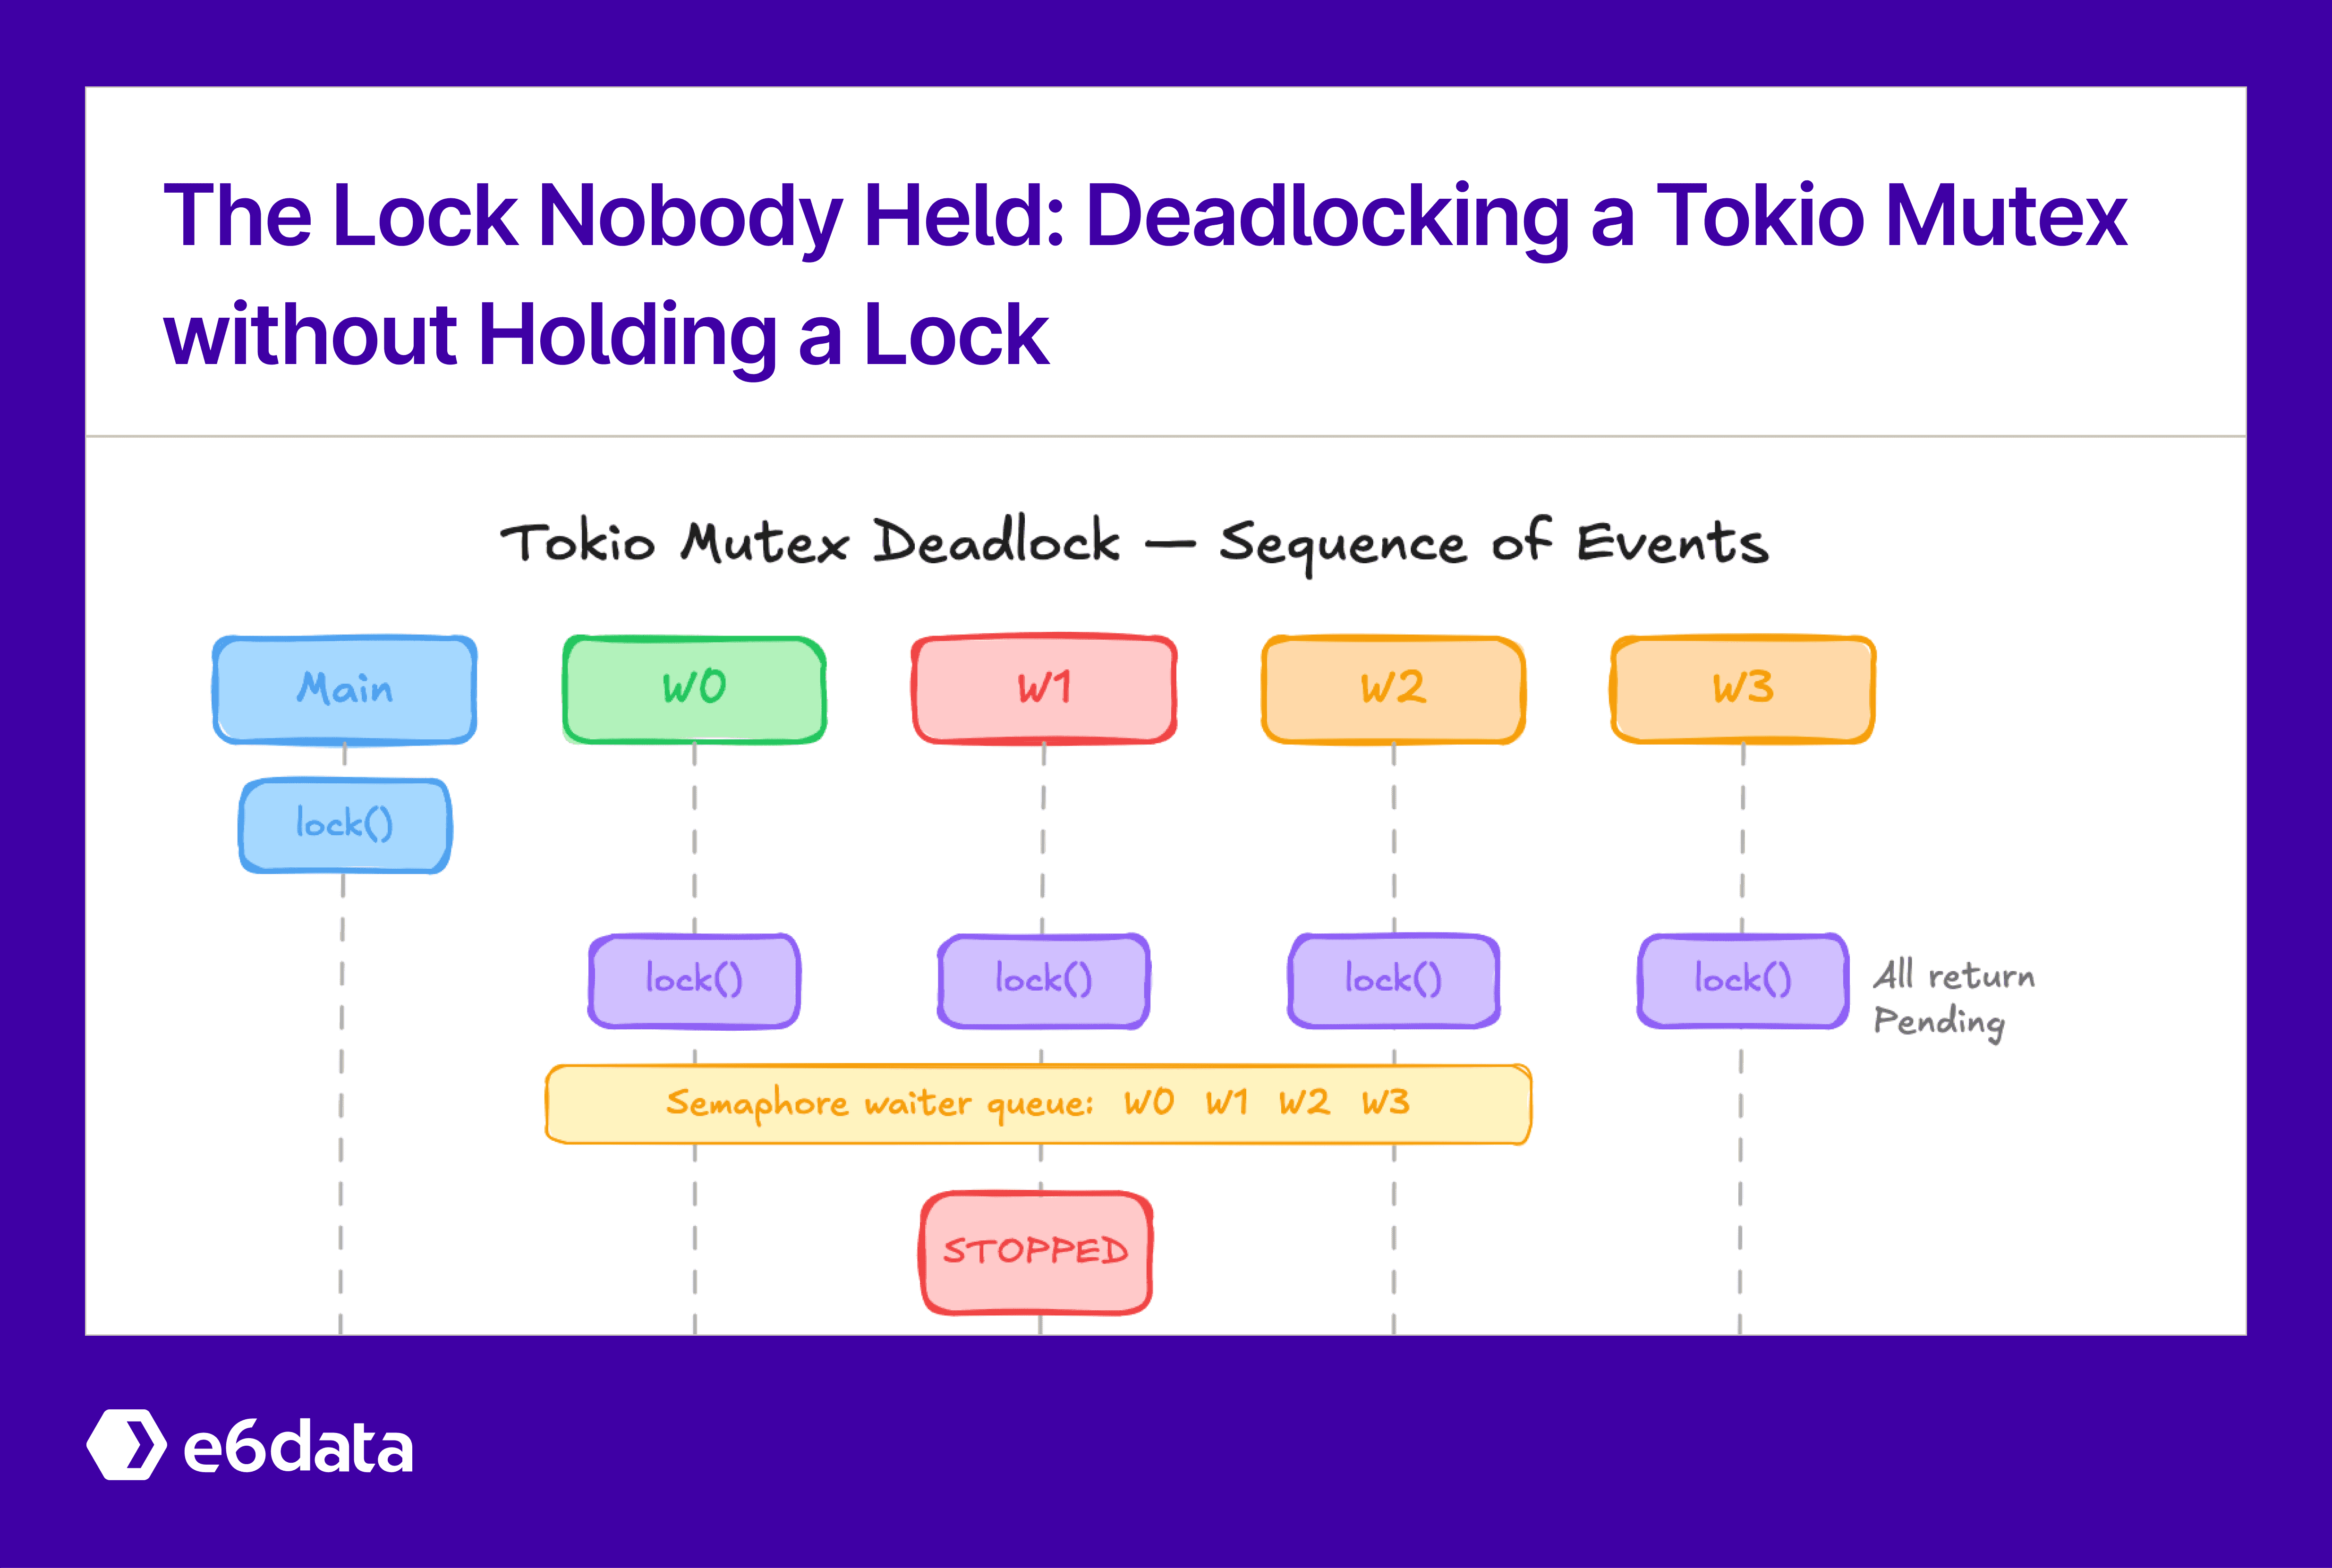
The Lock Nobody Held: Deadlocking a Tokio Mutex Without Holding a Lock
This post explains a subtle async Rust bug where tokio::sync::Mutex appears to deadlock despite logs showing the lock was released. The real issue is a wrapper future that stops polling its inner future after wake-up, violating the waker contract and trapping the semaphore permit inside Tokio’s waiter queue. The article walks through the reproducer, reframes why the Coffman conditions seem misleading here, and ends with practical fixes: pause or cancel work only at safe boundaries, or refactor critical sections to avoid holding async locks across .await.
Engineering · Oct 16, 2025
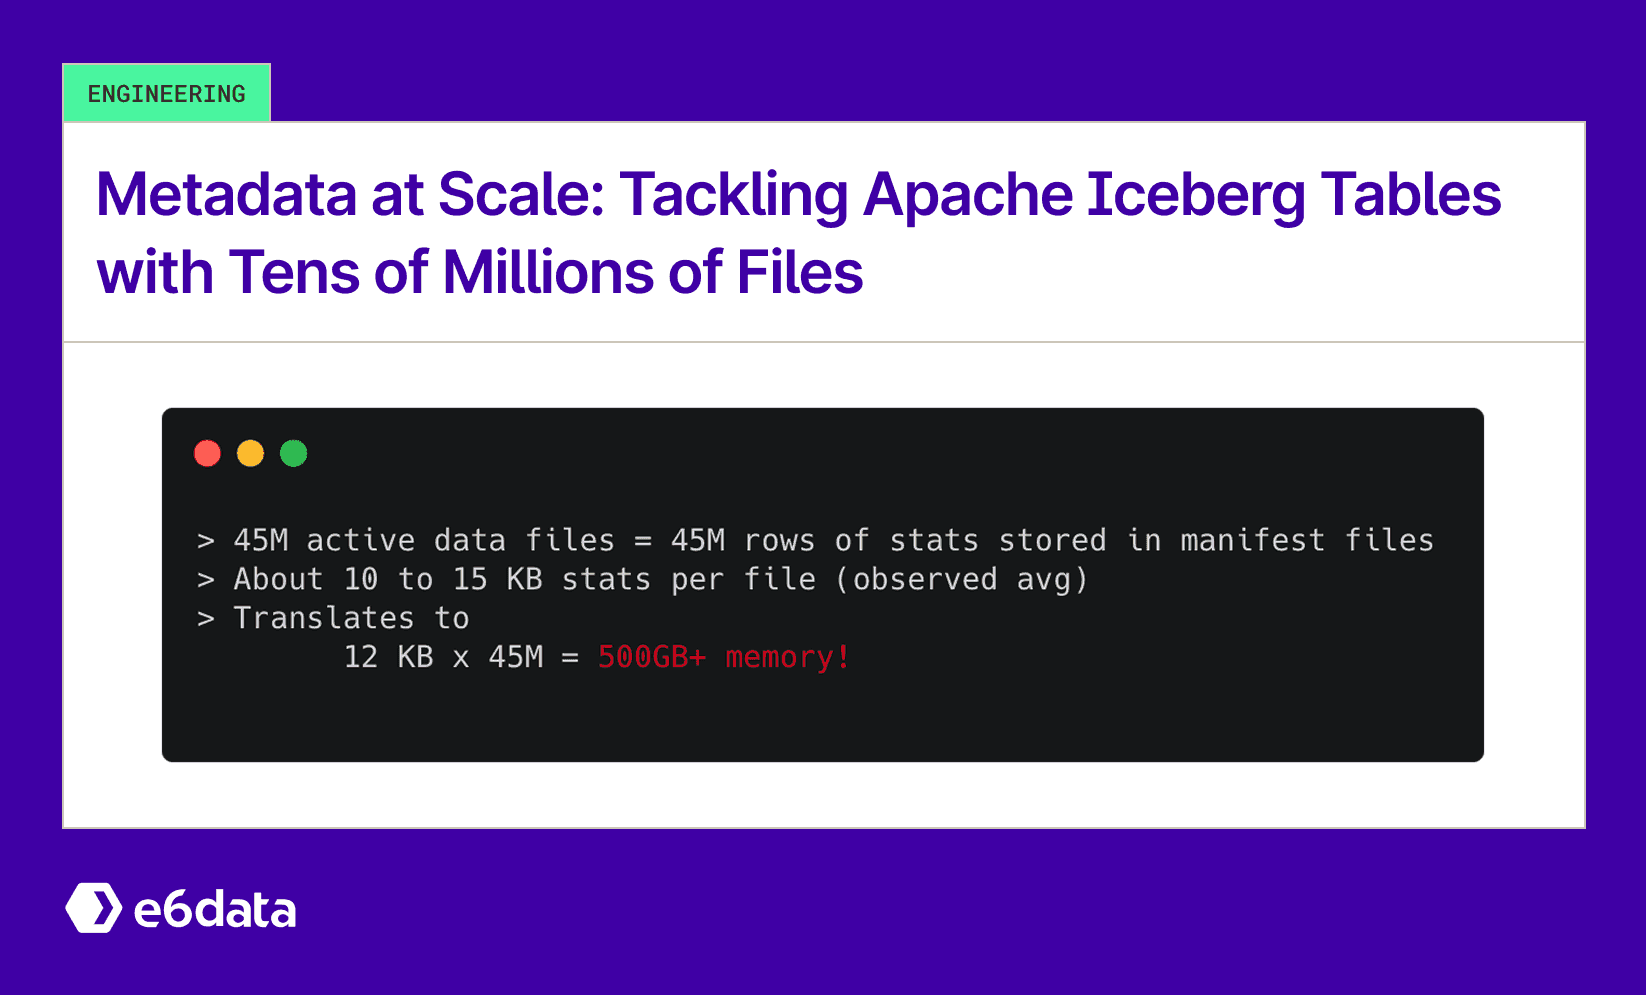
Metadata at Scale: Tackling Apache Iceberg Tables with Tens of Millions of Files
Apache Iceberg can OOM during planning when the file count inflates the metadata to terabytes. Fix it by streaming metadata reads (bounded batches), layered pruning (manifest-list → file-level), and treating metadata as queryable data to push down filters and project only needed stats—turning minutes or failures into seconds.
Engineering · Oct 10, 2025
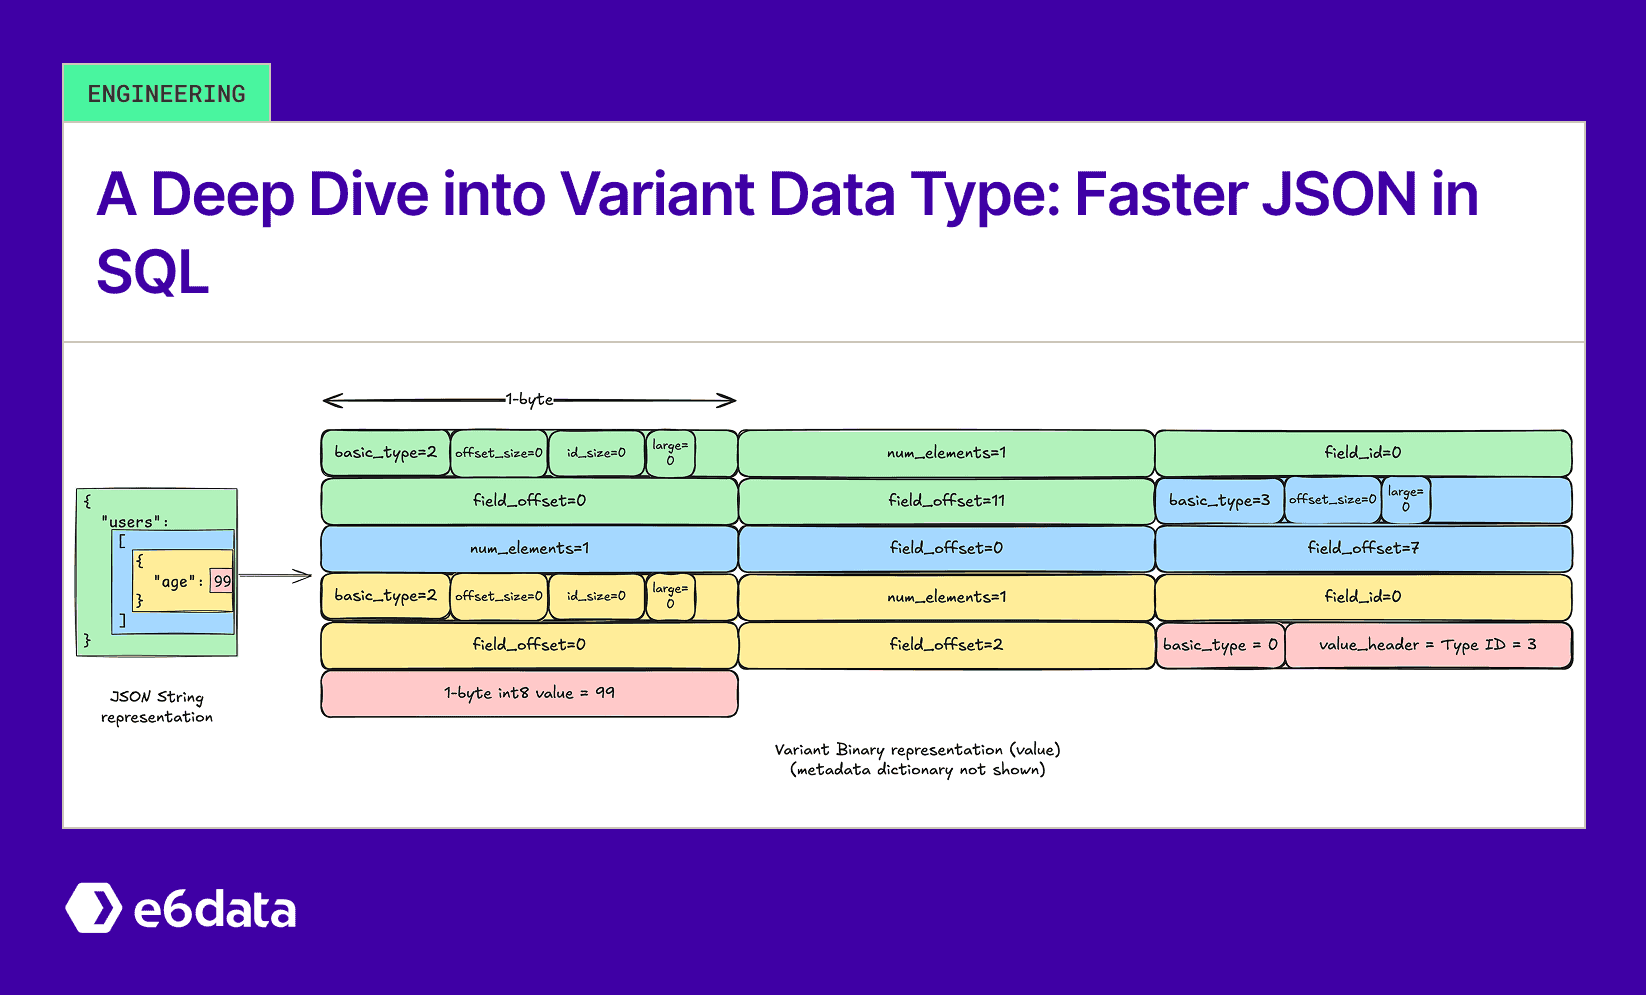
Faster JSON in SQL: A Deep Dive into Variant Data Type
The Variant data type stores semi-structured JSON in a binary, self-describing format with a per-row key dictionary (“metadata”) and compact values. Engines can jump directly to fields by path, avoiding full JSON parses. The result is flexible schema-on-read with significantly faster queries than plain JSON strings.
Engineering · Sep 19, 2025
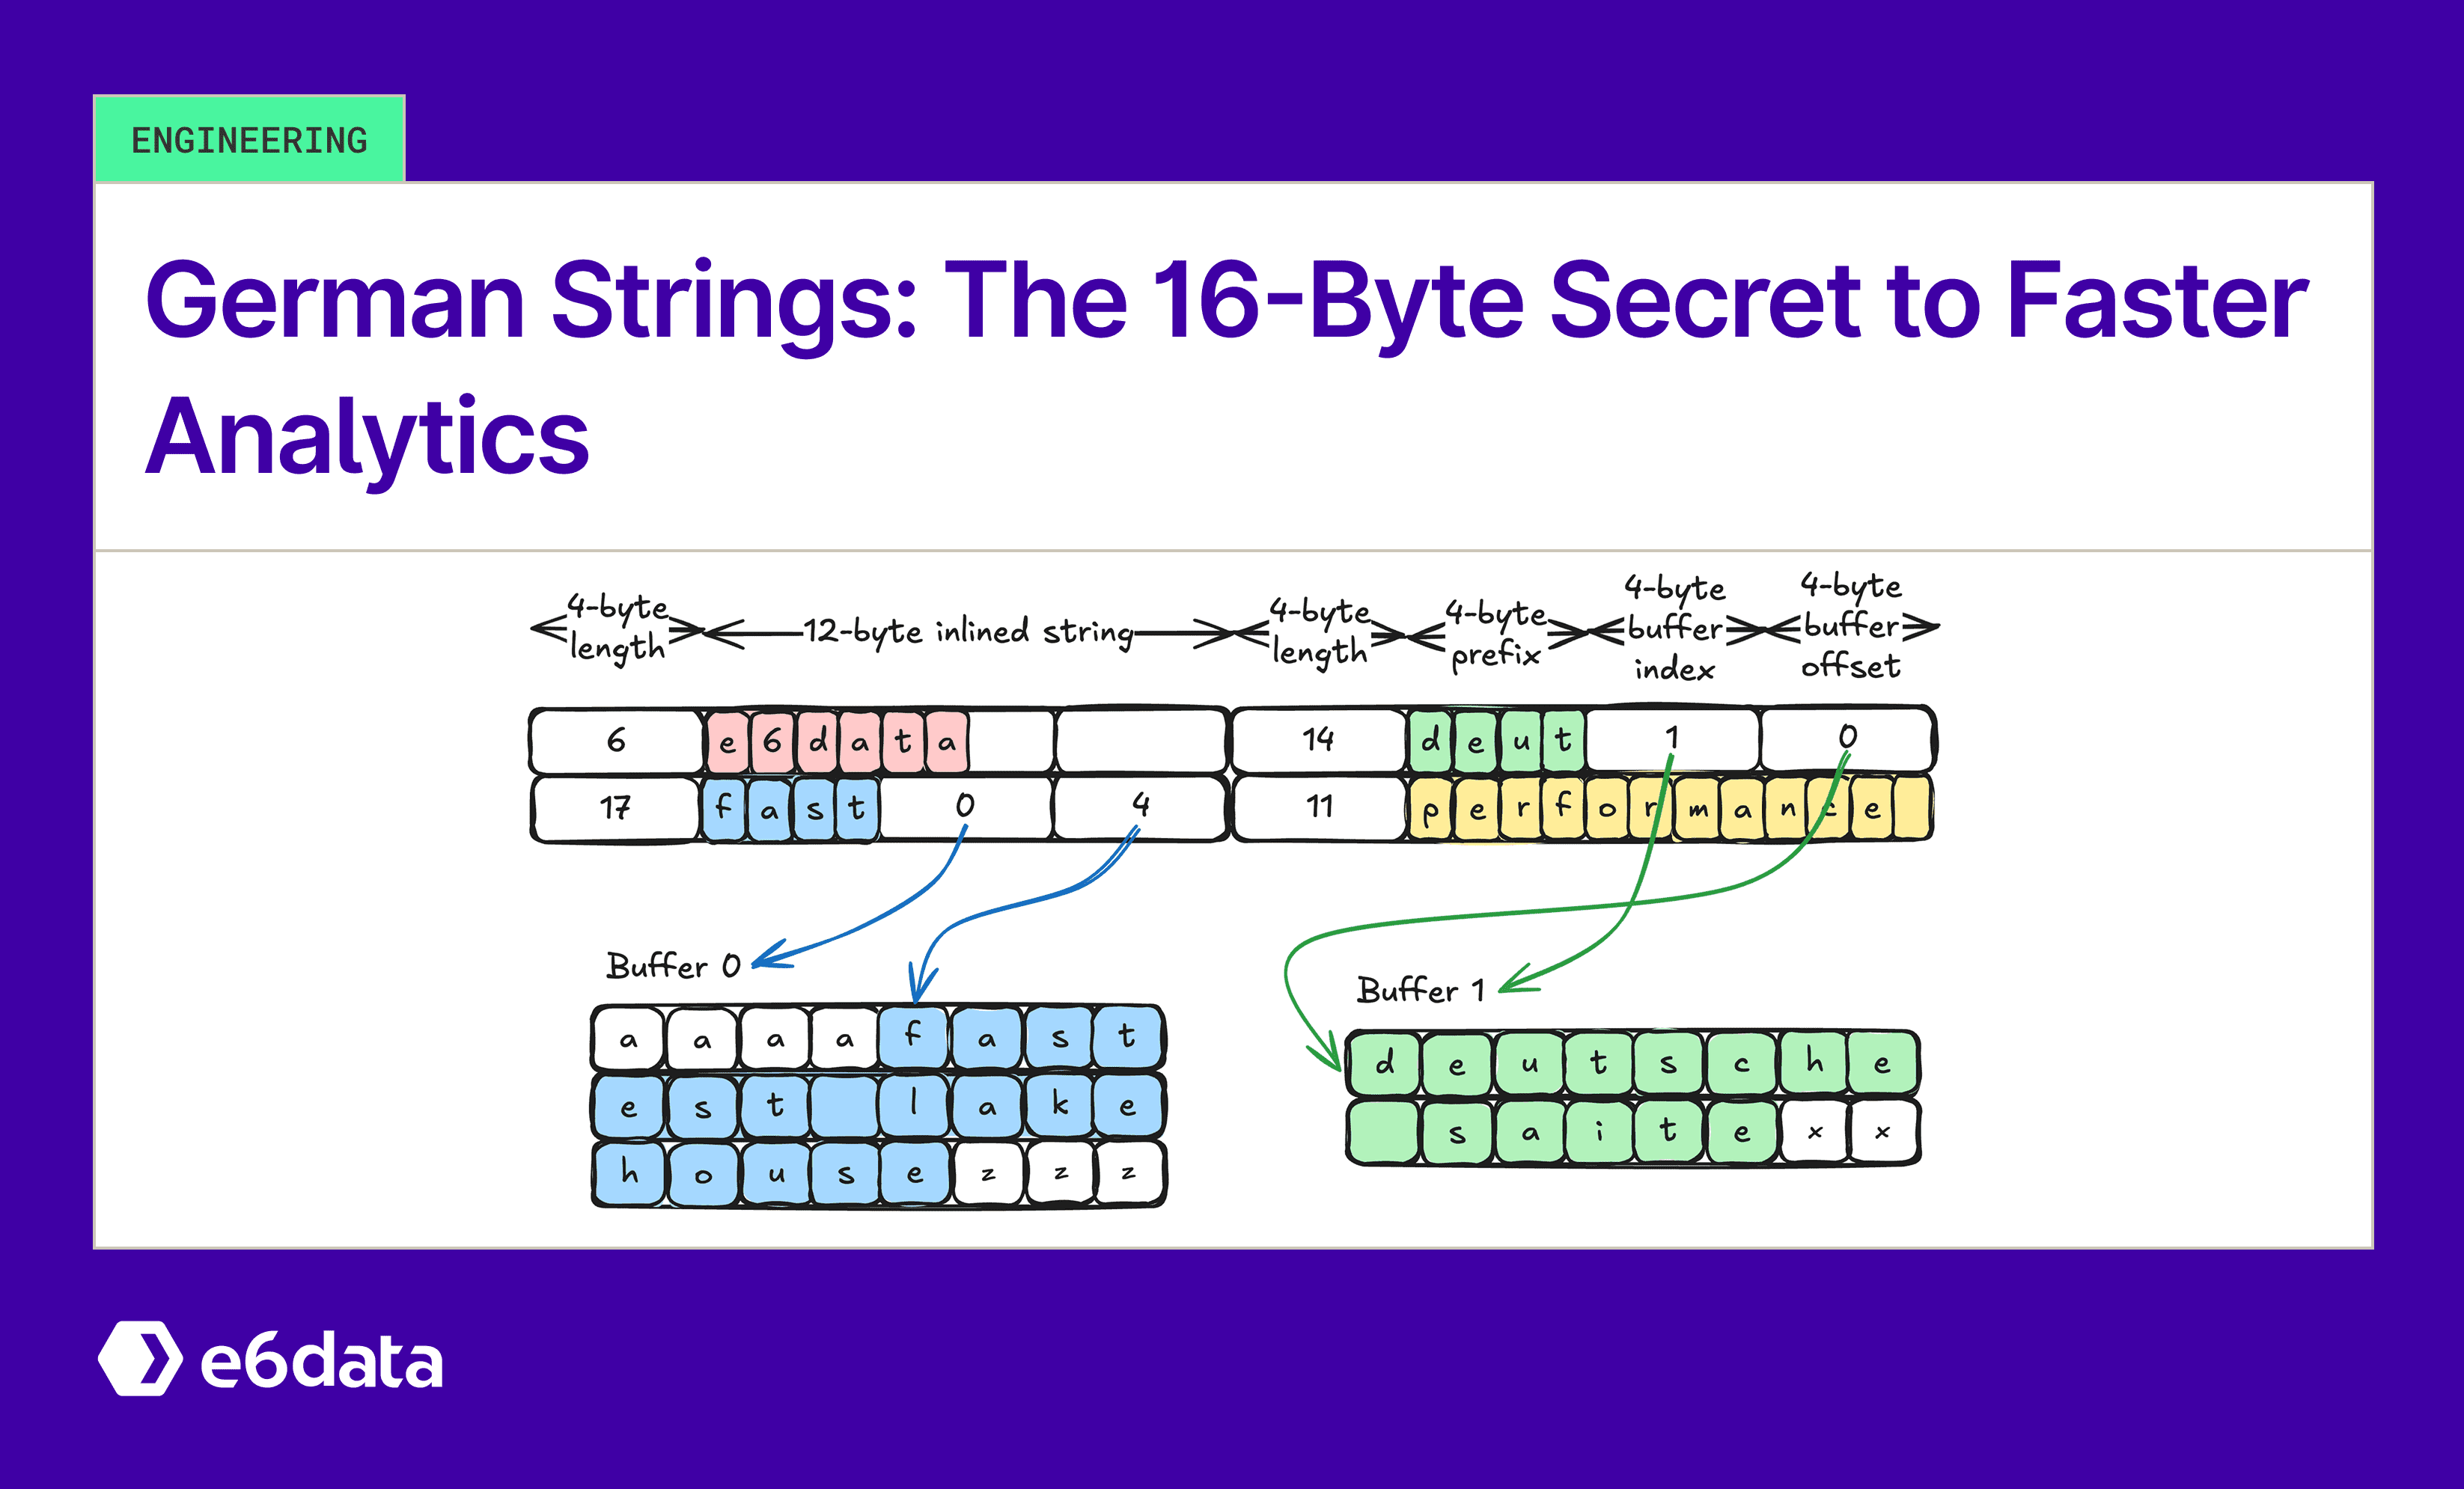
German Strings: The 16-Byte Secret to Faster Analytics
e6data’s blog explains how German Strings improve string performance in real-time analytics by replacing pointer-heavy strings with a compact 16-byte string struct. The layout stores length and an inline string prefix, so equality checks, joins, and prefix comparisons short-circuit on those bytes, boosting cache locality and reducing pointer dereferences. We show how Arrow’s StringView represents short strings fully inlined and long strings via buffer index and offset, enabling fewer copies, reuse of repeated values, and faster ingestion from Parquet. The post details benefits, trade-offs, and our implementation results: up to 3 to 3.5x speedups in microbenchmarks and consistent gains in string-heavy workloads. Readers learn when the optimization shines, how immutable strings and columnar processing help, and where adoption appears in Apache Arrow and DataFusion. If you care about query latency, throughput, and memory efficiency, this walkthrough gives a practical path to making text behave more like numbers with German Strings.
Engineering · Sep 12, 2025
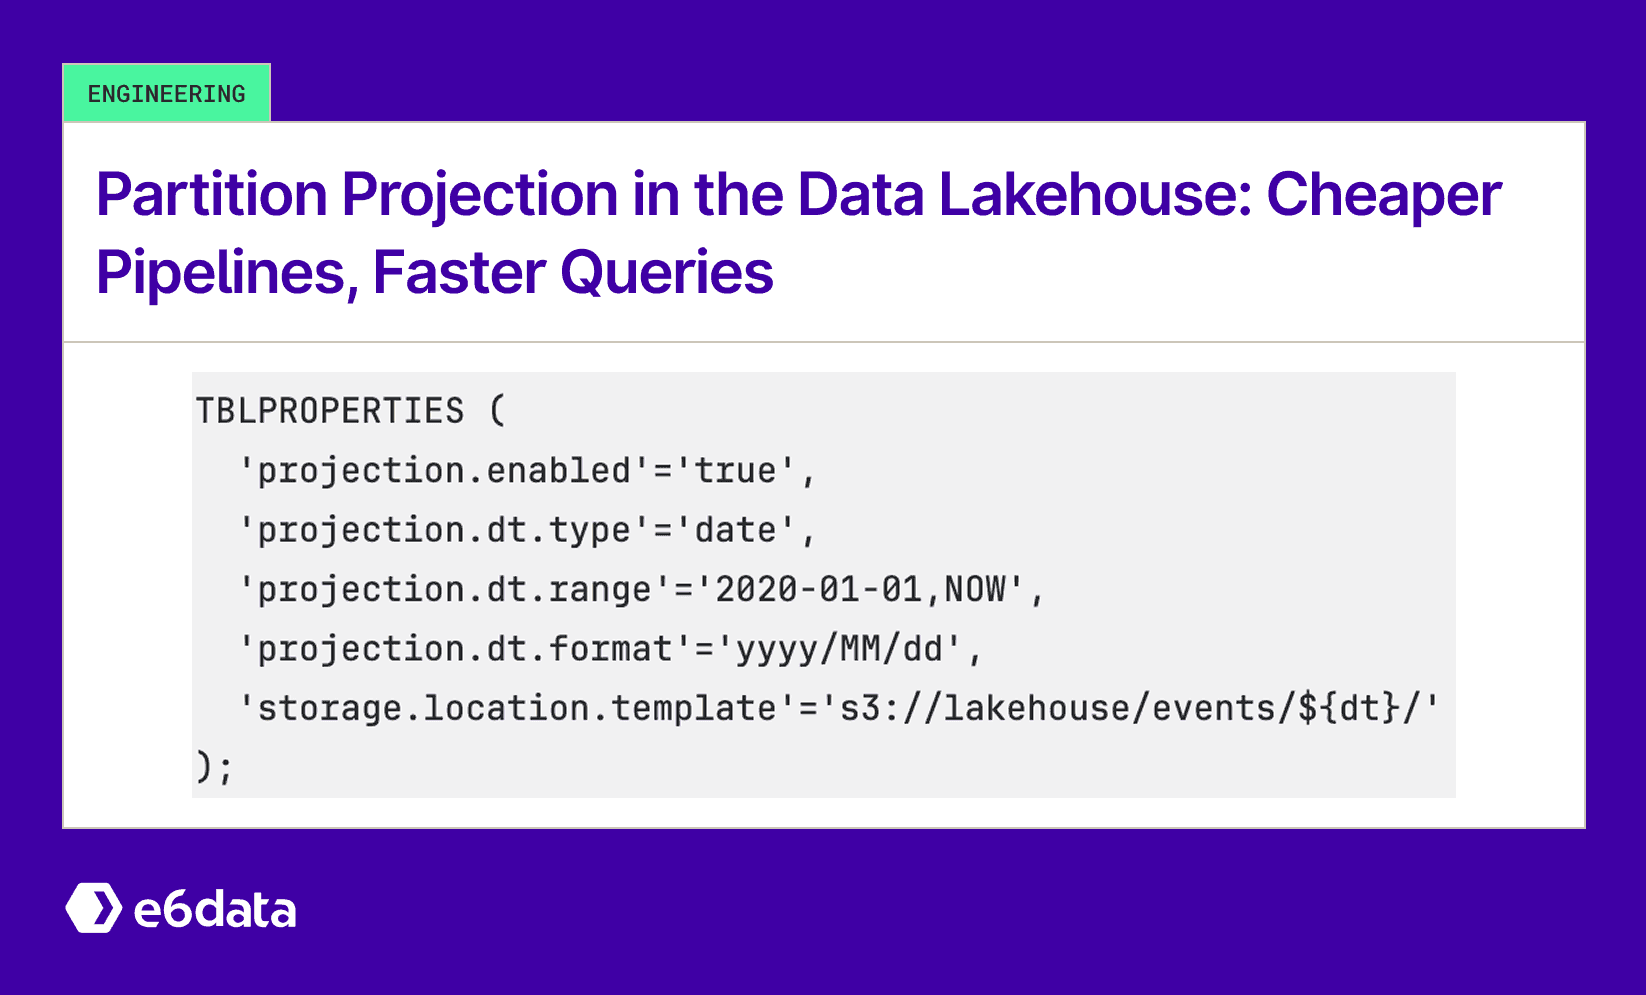
Partition Projection in the Data Lakehouse: Cheaper Pipelines, Faster Queries
Partition projection replaces manual, Hive-style partition registration with rule-based metadata that query engines compute on the fly. You keep the benefits of partition pruning while eliminating crawler/repair jobs and bloated catalog metadata, which cuts ETL costs and speeds up queries across cloud-agnostic data lakehouse platforms.
Engineering · Aug 8, 2025
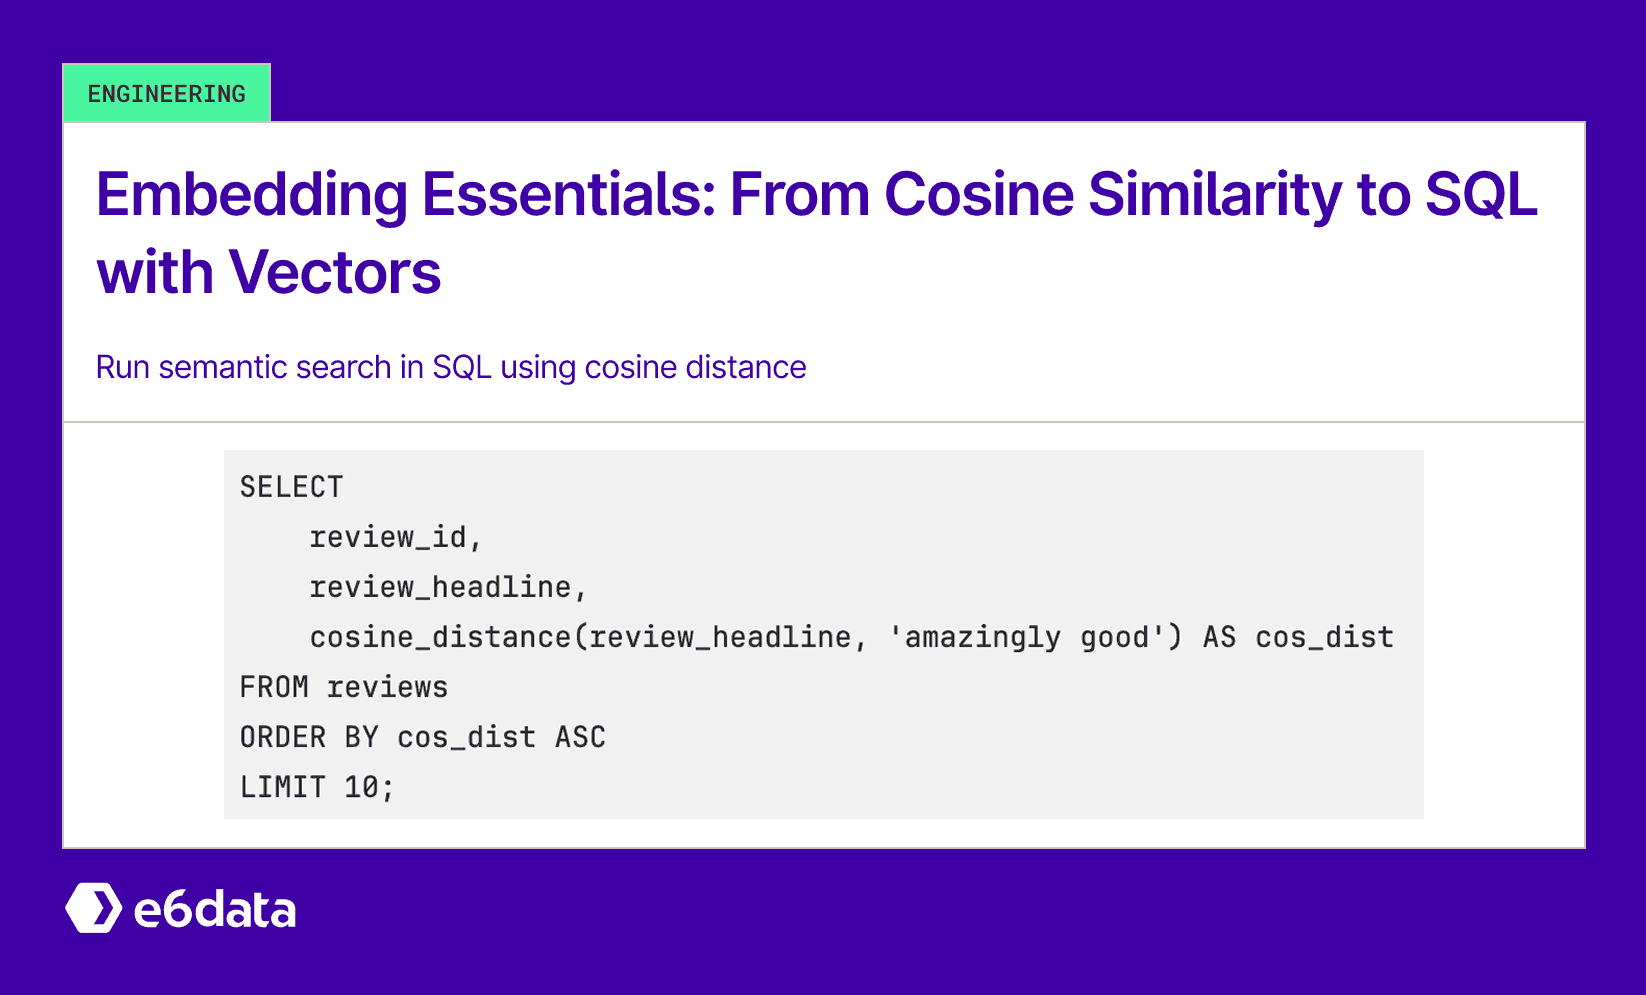
Embedding Essentials: From Cosine Similarity to SQL with Vectors
Run semantic search in SQL with cosine similarity and without a separate vector DB. e6data’s LOAD VECTOR and Blitz handle on-the-fly embeddings, quantized pruning, and precise reranking. The post compares MiniLM, SciBERT, CodeBERT, and shares quick tips on thresholds Vs. top-K for accurate, sub-second results.
Product · Aug 5, 2025
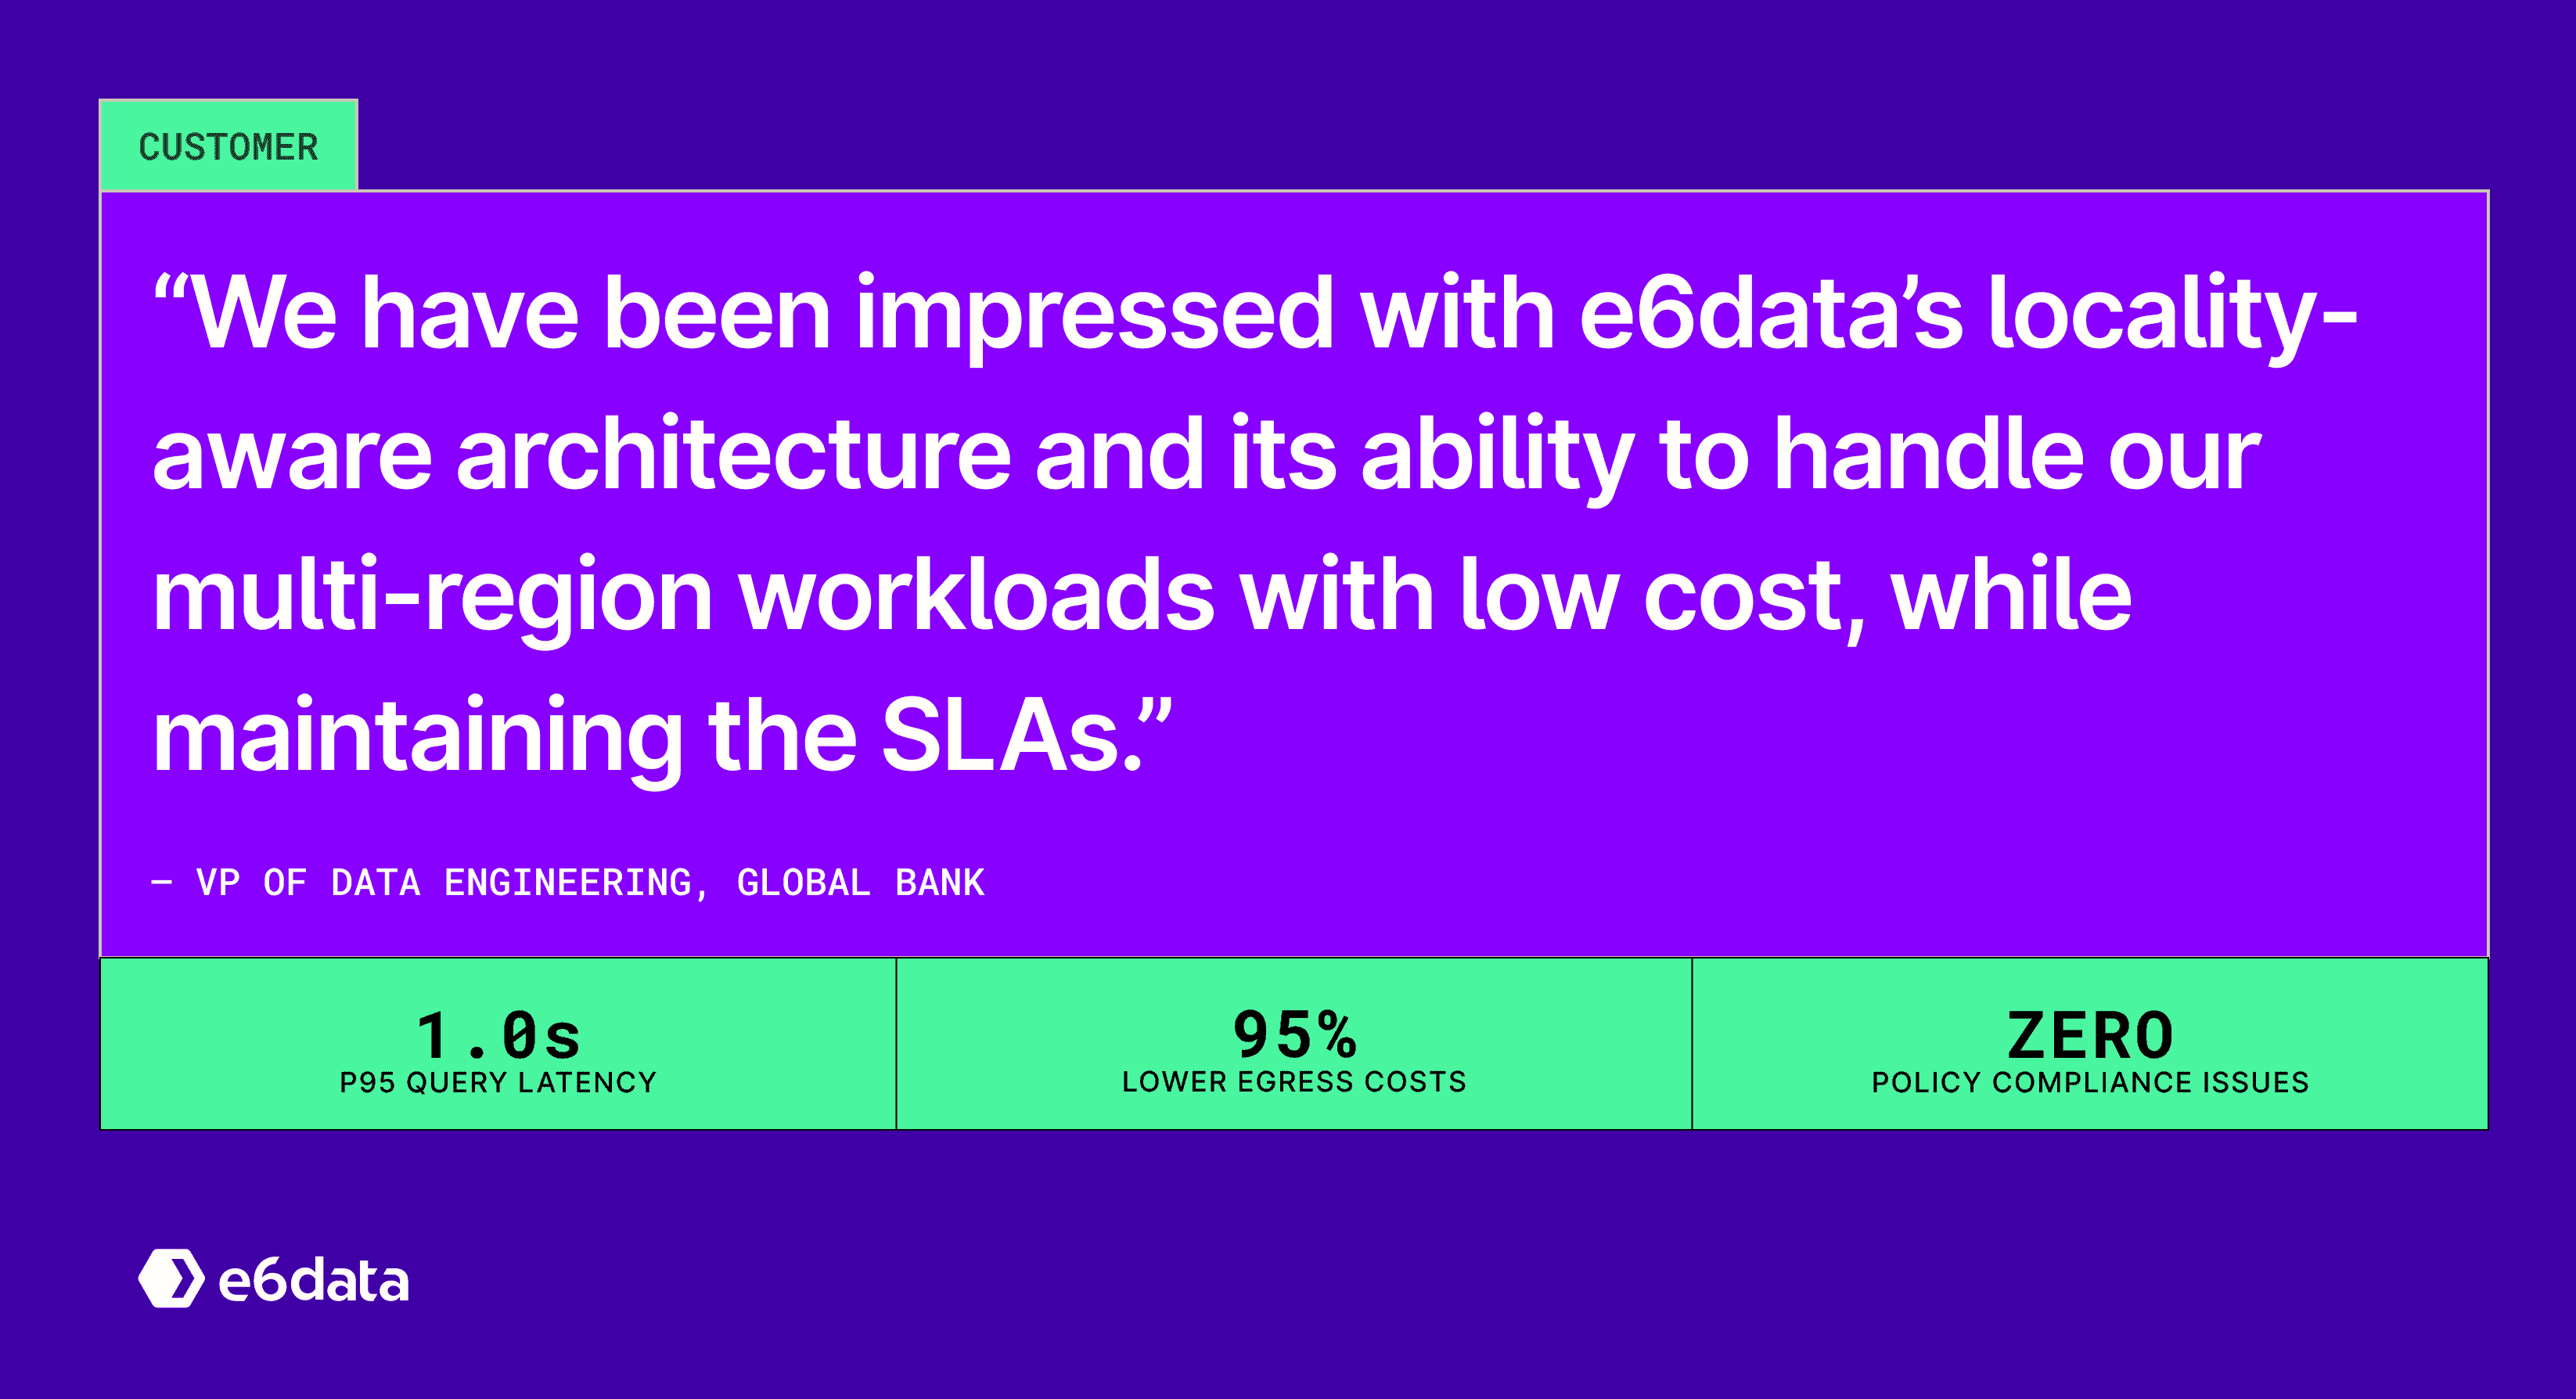
e6data’s Hybrid Data Lakehouse: 10x Faster Queries, Near-Zero Egress, Sub-Second Latency
e6data’s hybrid lakehouse keeps compute beside the data across AWS, Azure, GCP, and on-prem, wiping out cross-region egress charges and reducing query times by up to 10x. A location-aware scheduler plus open table formats (Parquet, Iceberg, Delta) avoids vendor lock-in, while a single IAM hook streamlines governance.
Engineering · Jul 25, 2025
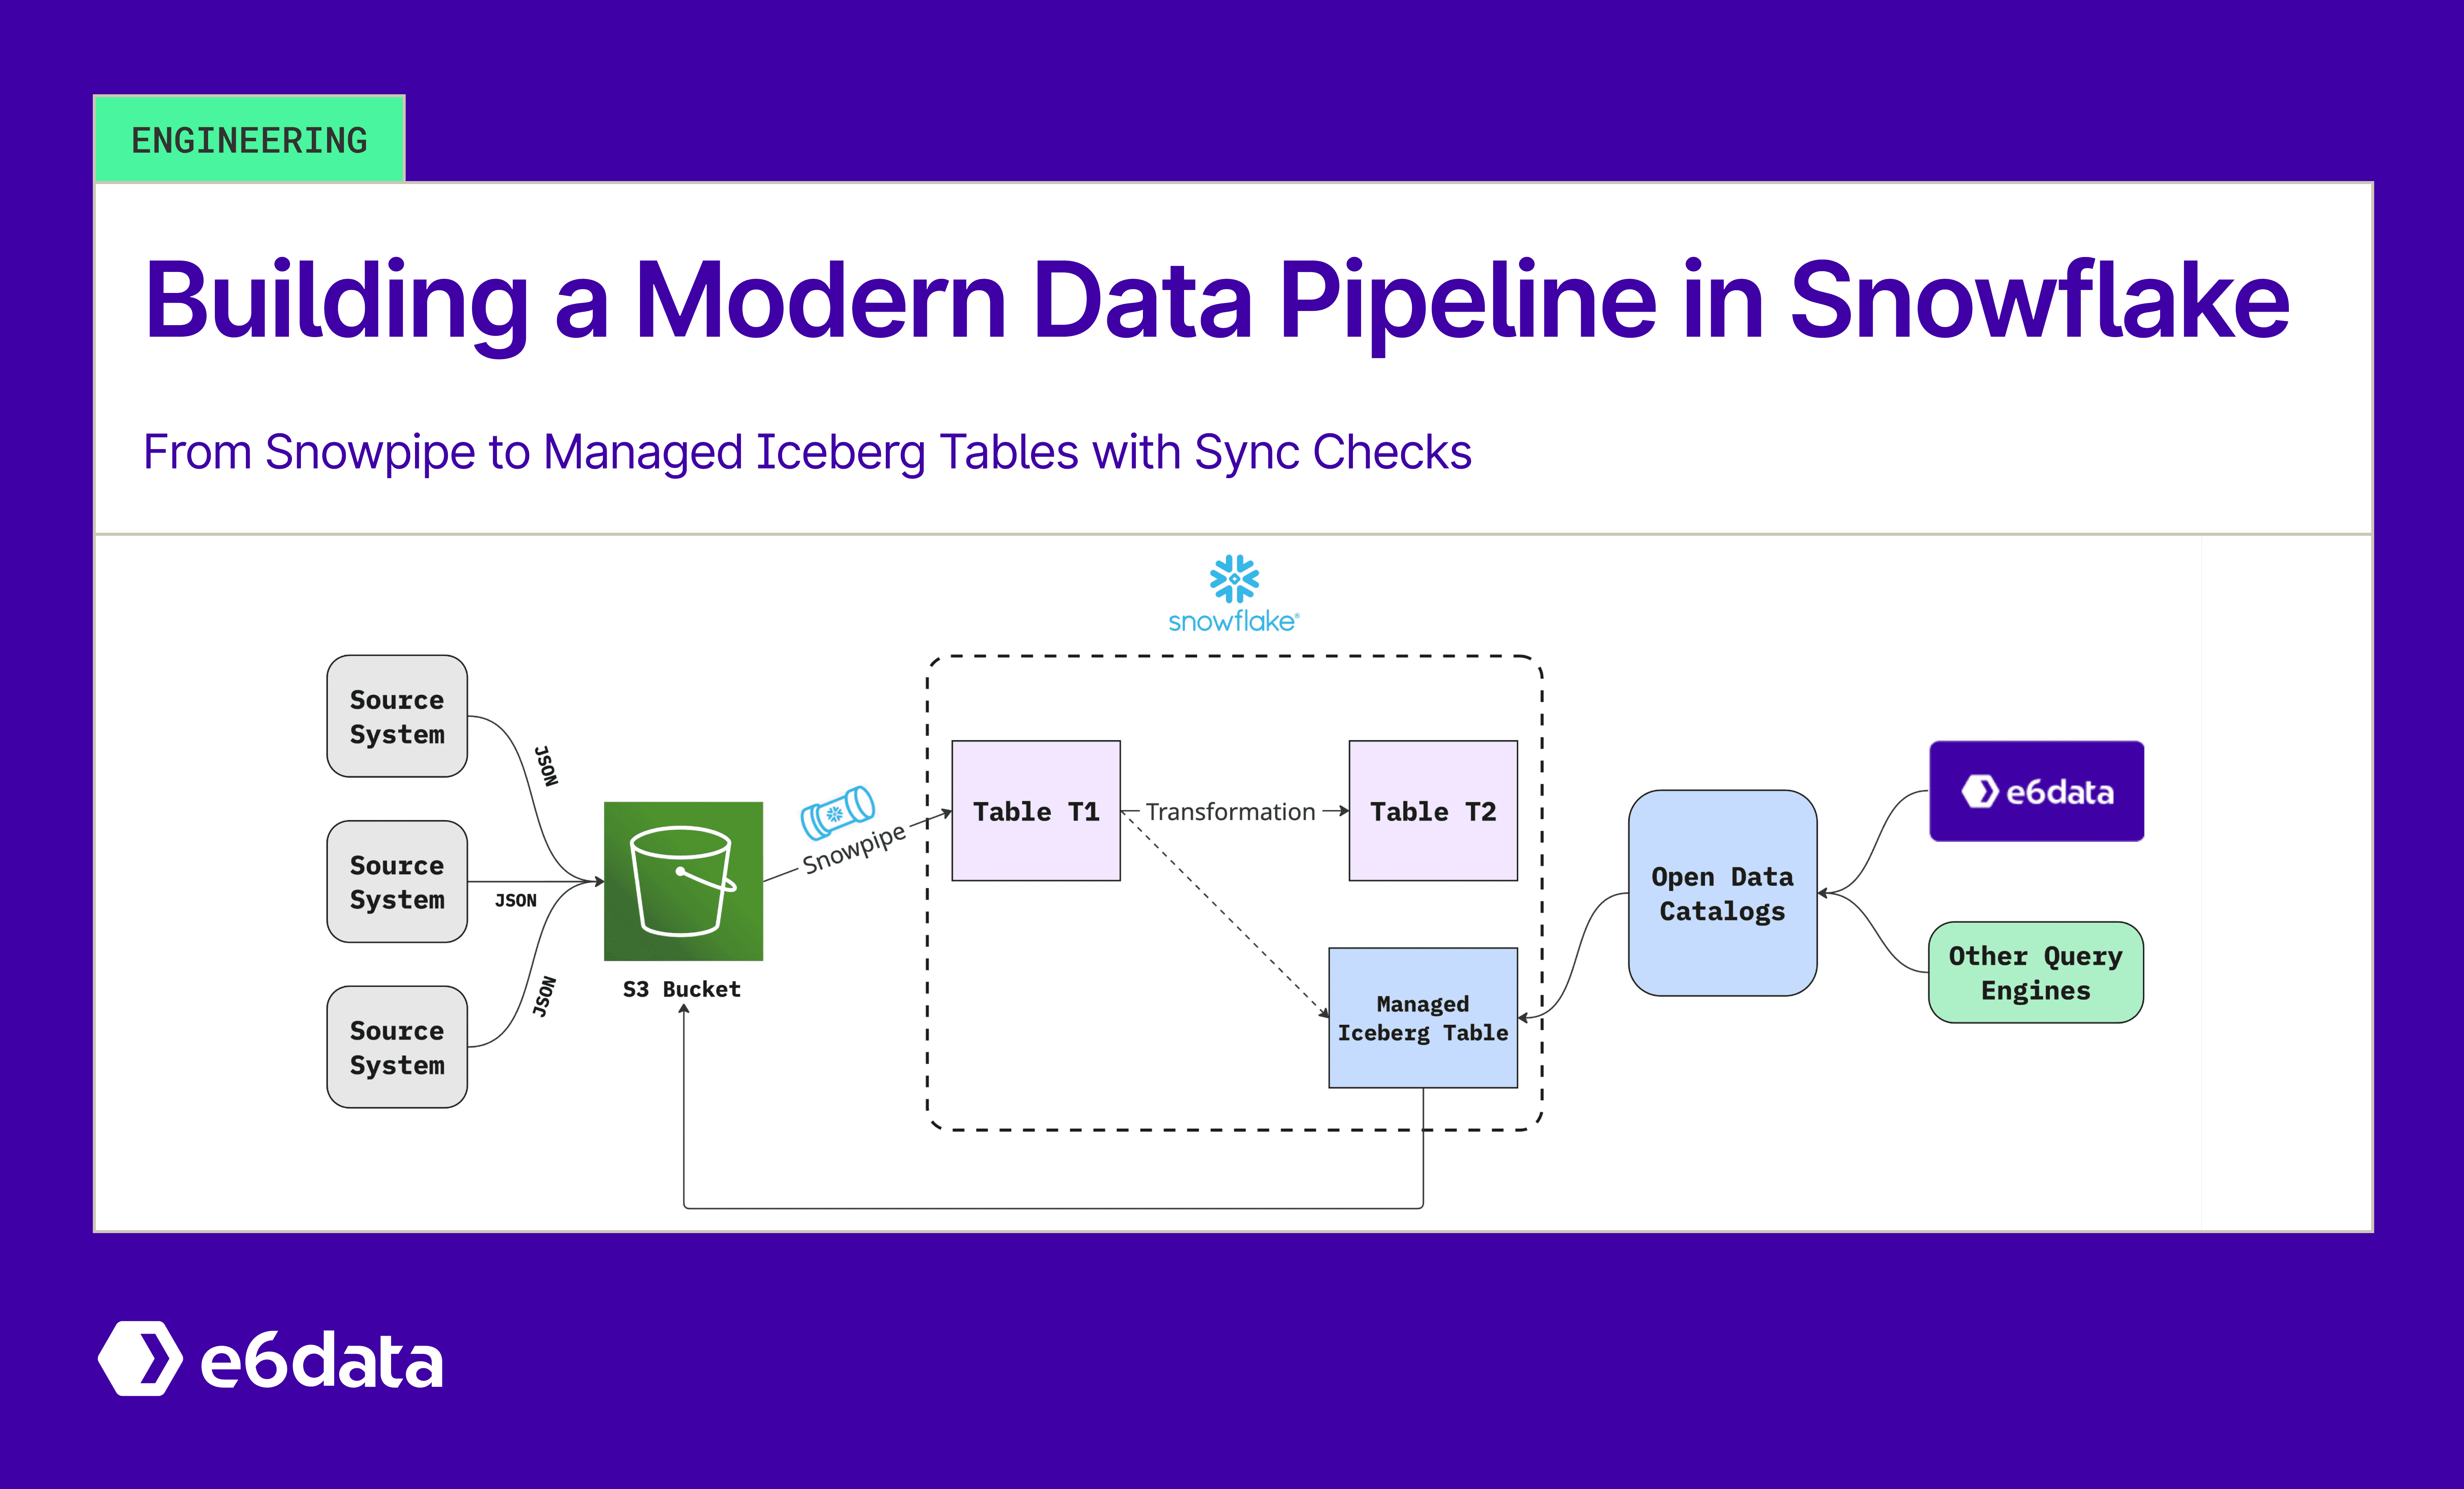
Building a Modern Data Pipeline in Snowflake: From Snowpipe to Managed Iceberg Tables with Sync Checks
This is a guide to building a lakehouse pipeline in Snowflake: Snowpipe auto‑ingests JSON orders to a landing table; a stored procedure cleans and transforms data into curated core tables, then writes to Snowflake‑managed Apache Iceberg tables stored as Parquet. We demonstrate how daily tasks trigger the procedure at 02:00 UTC and run sync checks, comprising row counts, set differences, and optional checksums, to ensure parity between core tables and Iceberg snapshots. The design combines Snowflake governance, SQL simplicity, and ACID performance with Iceberg’s open catalog, enabling multi‑engine analytics while avoiding vendor lock‑in.
Product · Jul 24, 2025
Improved open-table analytics stack with Iceberg, Polaris, Hudi, Delta Lake
Connect once, query everywhere. Our latest release provides advanced support for Apache Iceberg, Apache Polaris, Apache Hudi, and Delta Lake, enabling you to run fast SQL queries across every open table format without copying data or rewriting pipelines.
Engineering · Jul 18, 2025
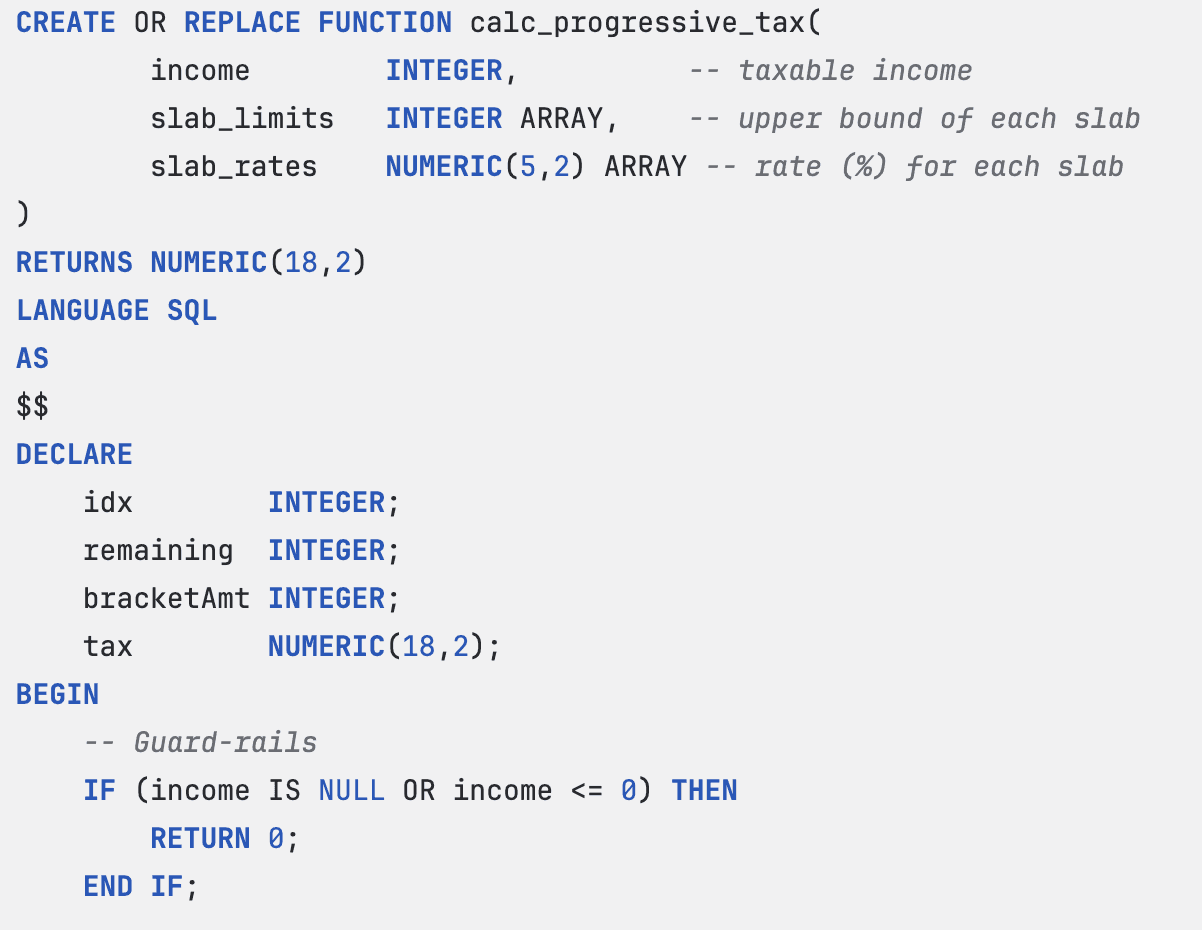
Procedural Power, Set-speed: Inside e6data’s Froid-inspired UDF Engine
Traditional multi-statement SQL User-Defined Functions give developers modular, expressive power but at the cost of brutal row-by-row execution and optimizer blindness. Drawing on Microsoft’s Froid research, e6data dissolves that performance tax: its new engine automatically inlines procedural UDF logic back into the set-oriented query plan, eliminating context switches and unleashing parallelism. The post explains why UDFs matter, dissects the pain points of inline vs. multi-statement functions, and shows how e6data fuses loops, variables, and branching logic into a single relational plan. The result is orders-of-magnitude speed-ups with no code changes, setting the stage for a deeper dive into the inlining algorithms in upcoming articles.
Engineering · Jun 27, 2025
Iceberg Catalogs 2025: A Deep Dive into Emerging Catalogs and Modern Metadata Management
The emerging Iceberg catalogs are reshaping metadata management strategies for 2025. From Git-style branching in Nessie to the lean Rust performance of Lakekeeper, a new wave of emerging catalogs: Nessie, Polaris, Gravitino, Lakekeeper, and Unity Catalog, are challenging the long-entrenched Hadoop, Hive, and Glue stores. Each promises cross-table transactions, fine-grained governance, and multi-engine freedom, answering developers’ calls for faster, safer lakehouse operations. DuckDB’s DuckLake shows how even SQL engines are entering the arena, while Apache Iceberg’s REST spec keeps everyone talking the same protocol. Whether you crave geo-distributed metadata, zero-copy isolation, or a single-binary deploy, the catalog war is far from over. And the winners will define how data engineers build lakehouses for years to come.
Engineering · Jun 11, 2025
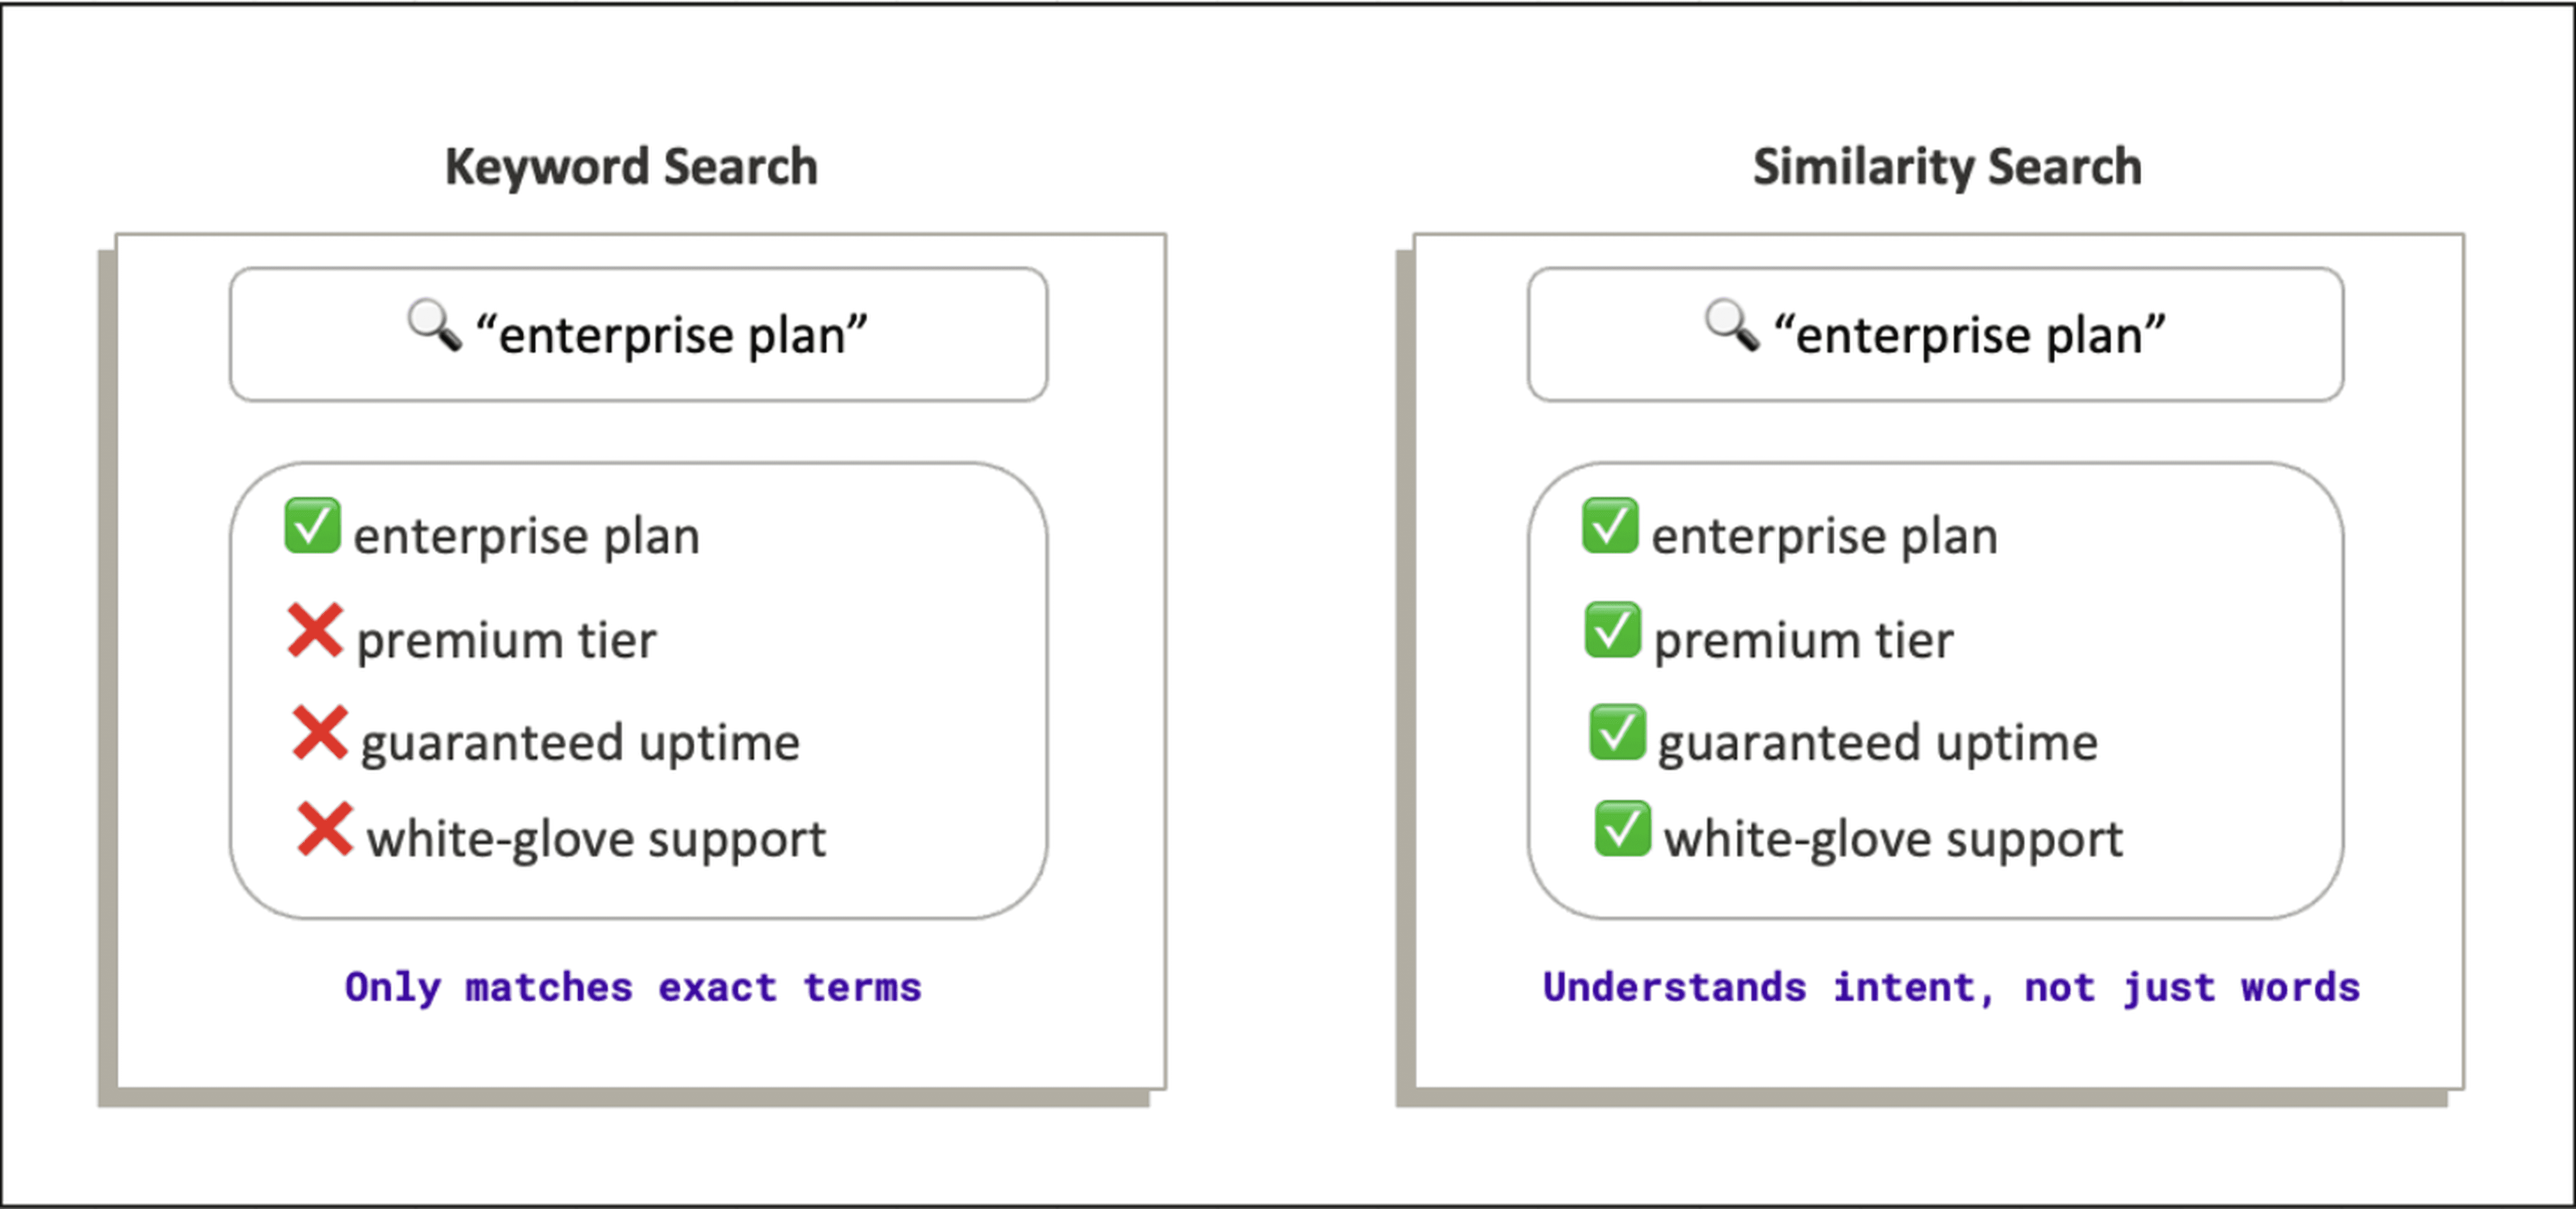
Vector & Semantic Search in the Lakehouse: Faster Insight from Unstructured Data
Vector and semantic search let lakehouse teams unlock 80% of enterprise data that lives in free-form text, images, and other unstructured formats. By embedding high-dimensional vectors directly into the SQL optimizer, e6data’s “Unify, Don’t Migrate” engine runs cosine-similarity joins faster without extra ETL or a separate vector database. The result: lower costs, simpler pipelines, and far richer insights from customer voice, support chats, docs, and more.
Engineering · Jun 6, 2025
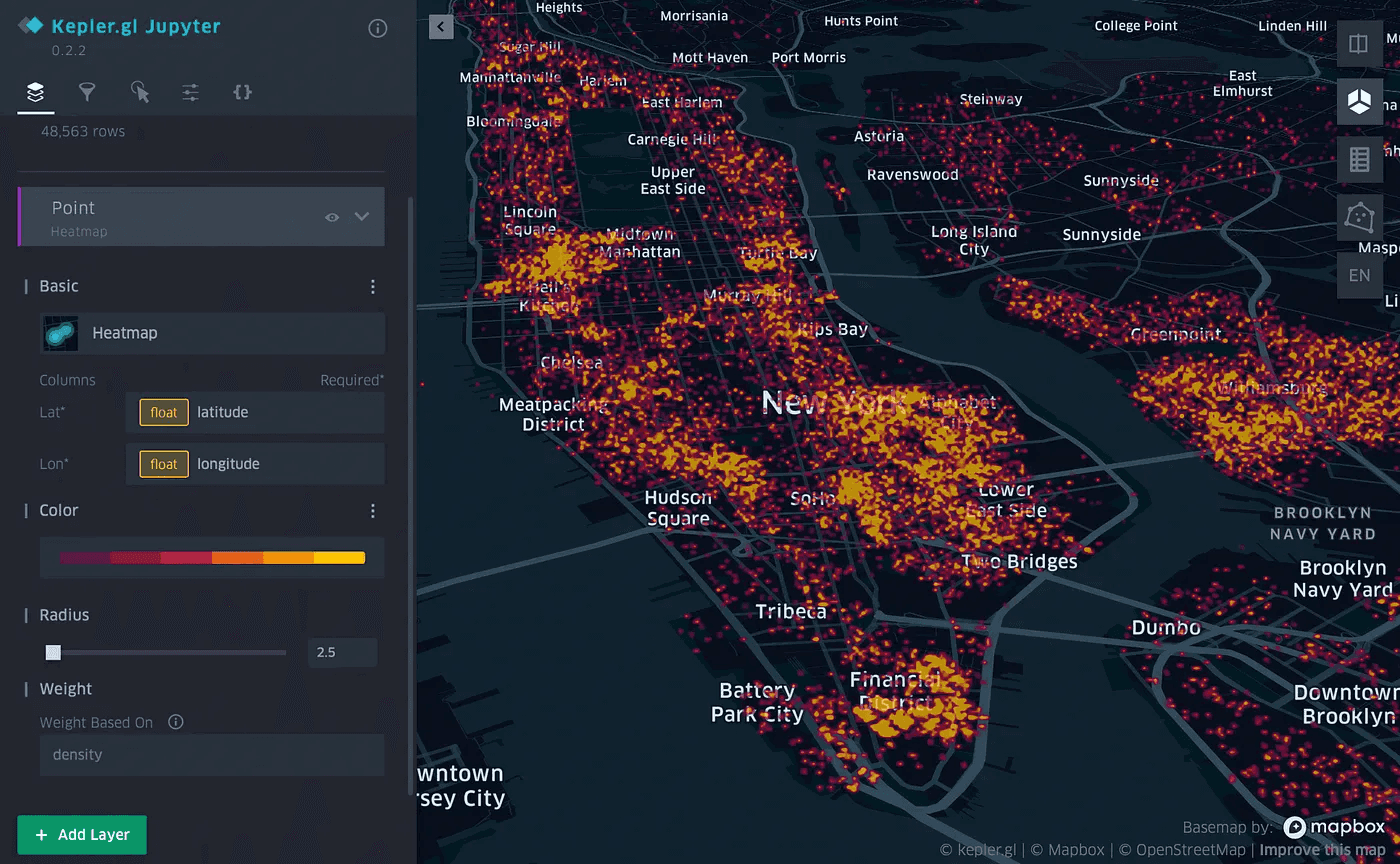
Solving Geospatial Analytics Performance Bottleneck: H3 vs Quadkey
Geospatial performance bottlenecks appear the instant a lat/lon B-tree creeps past a hundred million rows. This guide benchmarks H3 hex grids against Quadkey square tiles, shows how to hex-bin heat-maps, shard warehouses, and even stream 3-D voxel tiles on GPUs.
Company · Apr 23, 2025
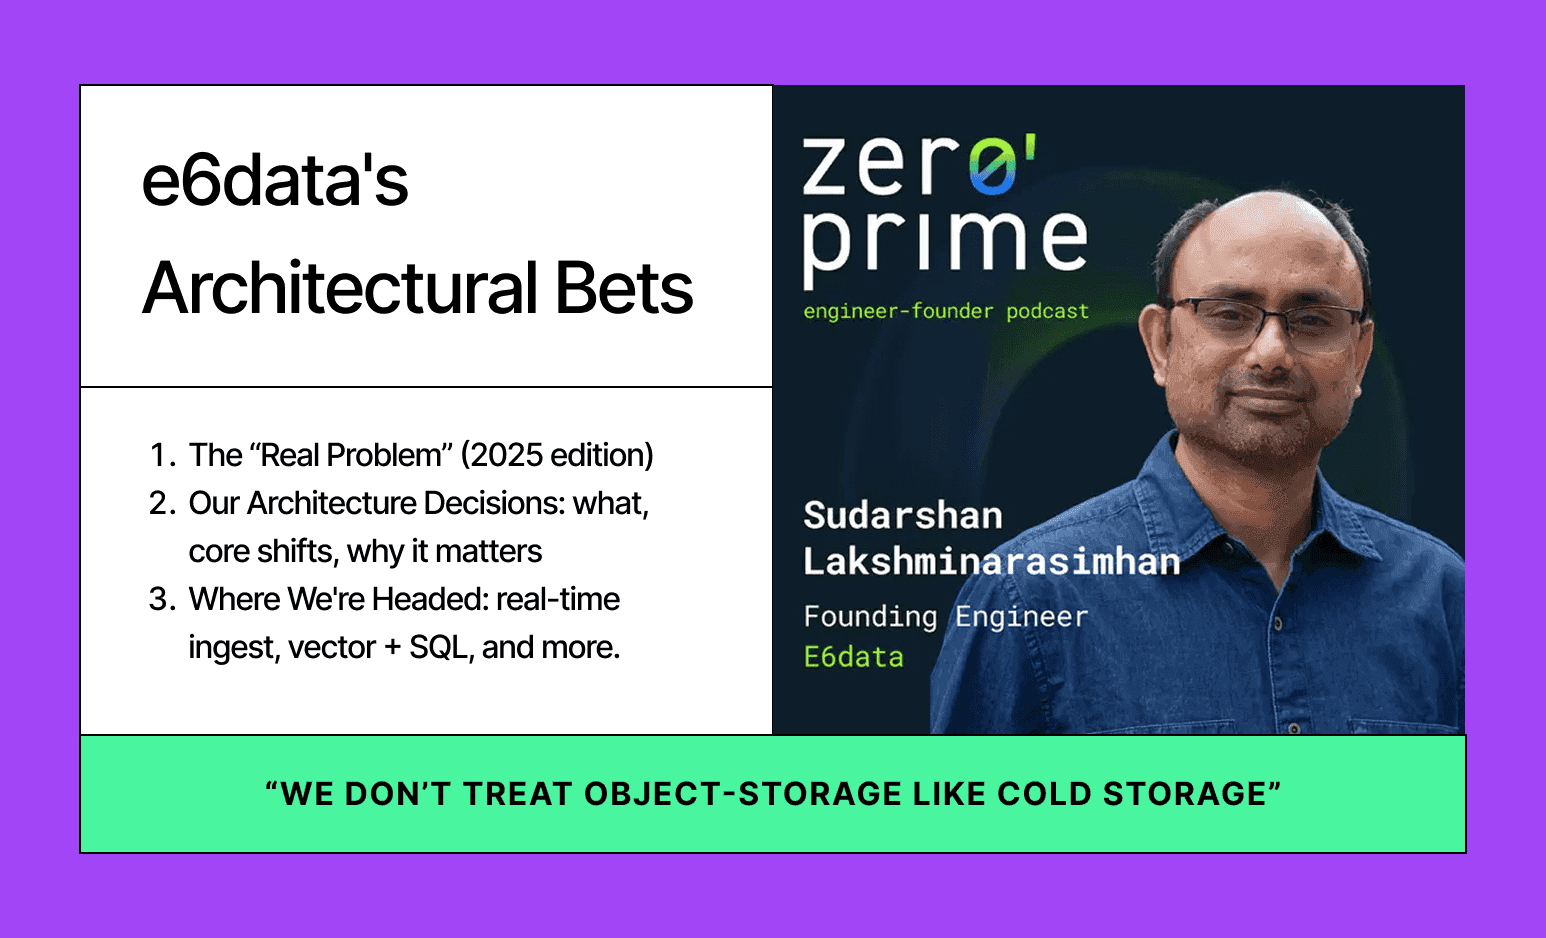
e6data’s Architectural Bets: our Head of Engineering’s conversation w/Pete at Zero Prime Podcast
e6data's founding engineer and Head of Engineering, Sudarshan Lakshminarasimhan, unpacks the internals of their compute engine on Zero Prime podcast
Engineering · Apr 23, 2025
Eliminating Redundant Computations in Query Plans with Automatic CTE Detection
How to implement detection of subgraphs within a query plan | Demonstrate pruning and cost-based decisions | Redundant computations | Automatic CTE
Product · Apr 16, 2025
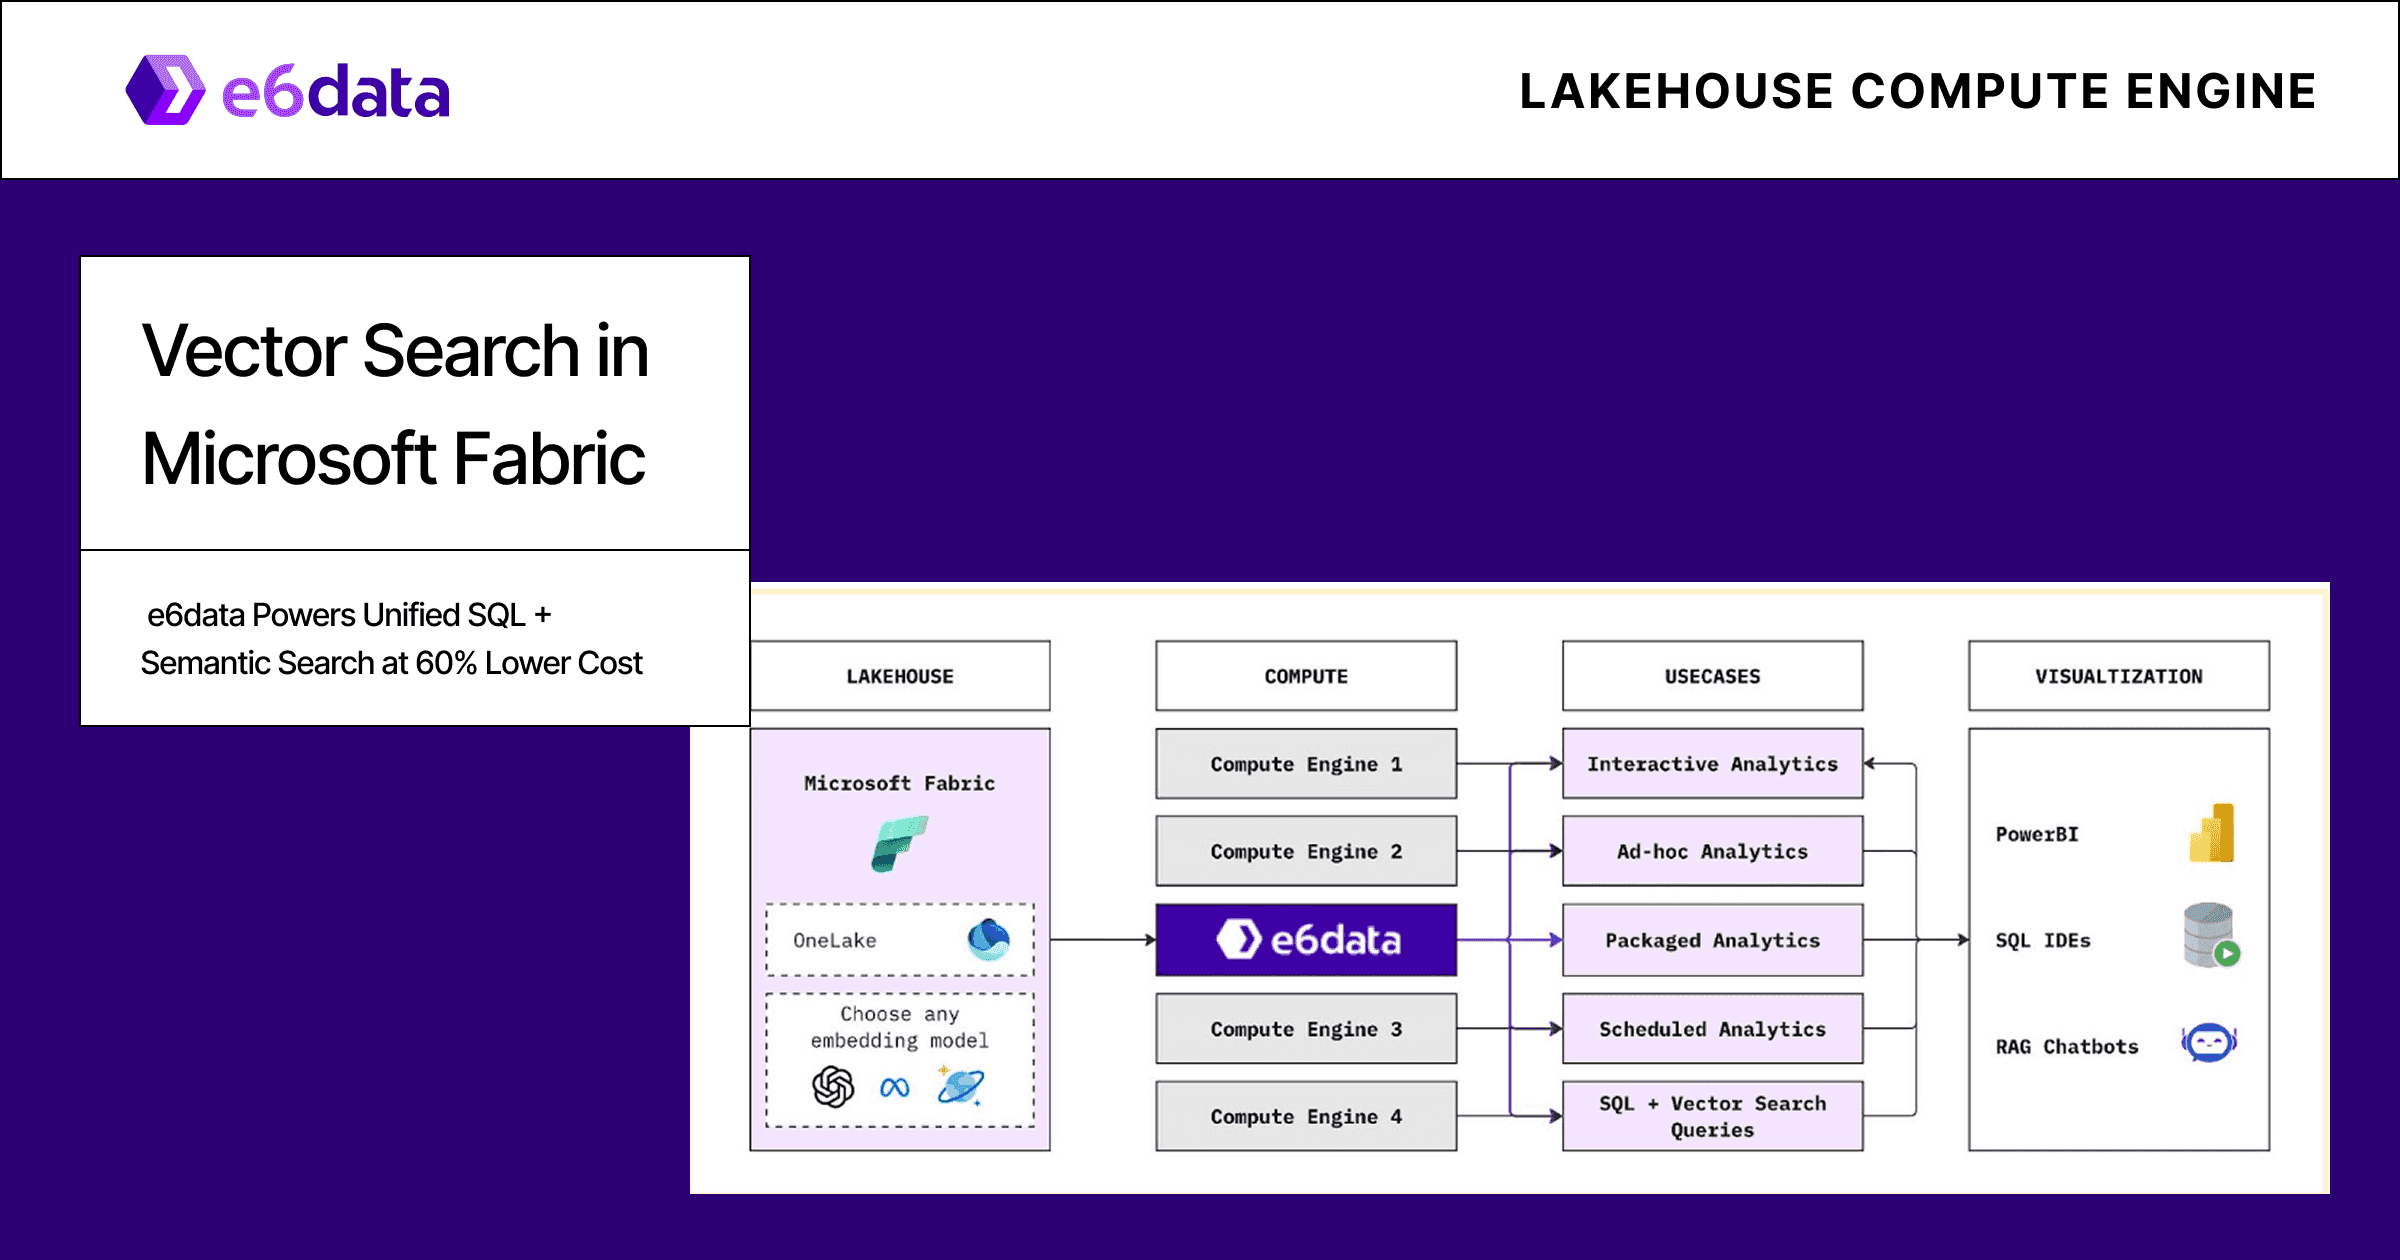
Vector Search in MS Fabric: e6data Powers Unified SQL + Semantic Search at 60% lower cost
e6data brings SQL and AI together, letting you query unstructured data directly in Microsoft Fabric 10x faster and 60% lower cost—no pipelines, no workarounds, just fast answers.
Product · Apr 14, 2025
e6data Integrates with S3 Tables: A New Era in Data Management
In today’s fast-paced world of data management, every organization is on the lookout for innovative ways to efficiently store, manage, and analyze large.
Engineering · Apr 3, 2025
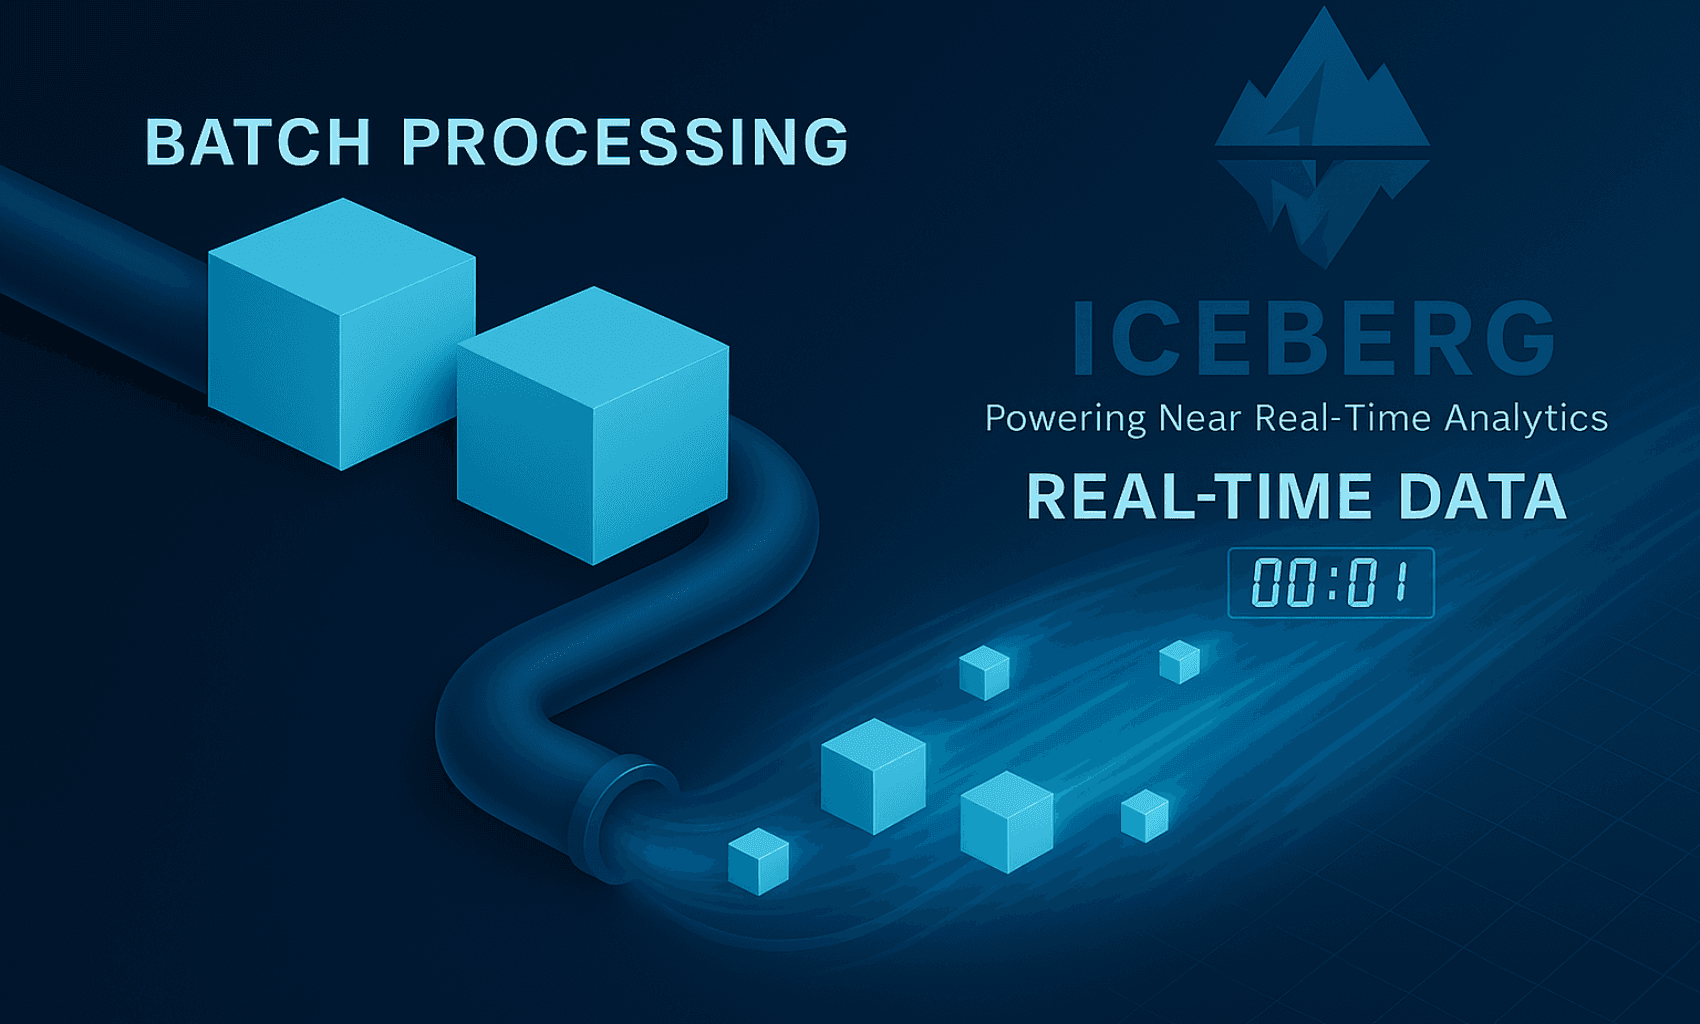
Beyond Batch: Architecting Fast Ingestion for Near Real-Time Iceberg Queries
Data analytics, as we know it, is undergoing a seismic shift. SQL query engines traditionally designed for batch workloads on Lakehouse architectures like.
Product · Apr 1, 2025
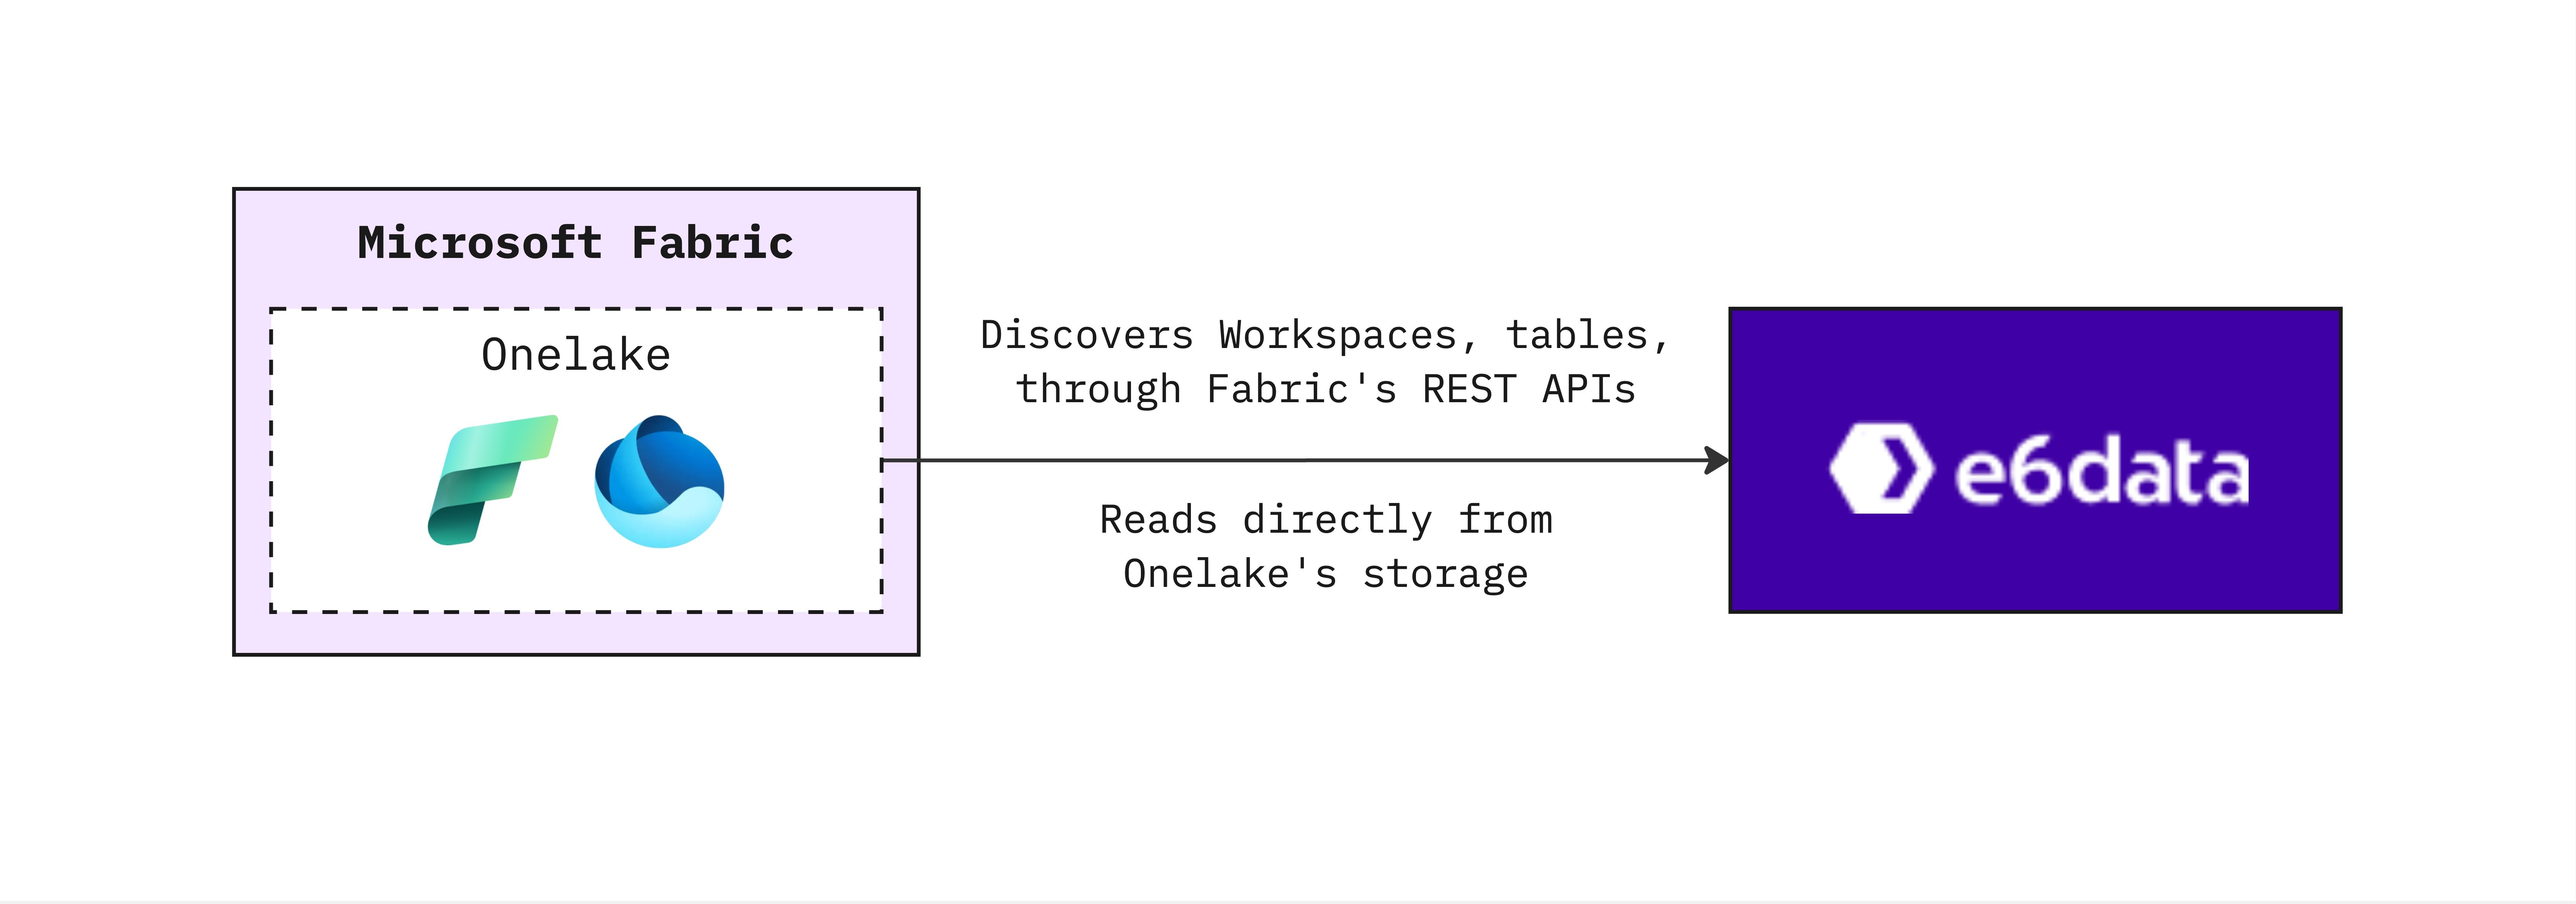
e6data with Microsoft Fabric: Faster Queries, Lower Bills - Without Leaving OneLake
Query your existing OneLake data about 33% faster, cutting analytics costs by 2-3x without changing your Fabric workflow.
Product · Mar 31, 2025
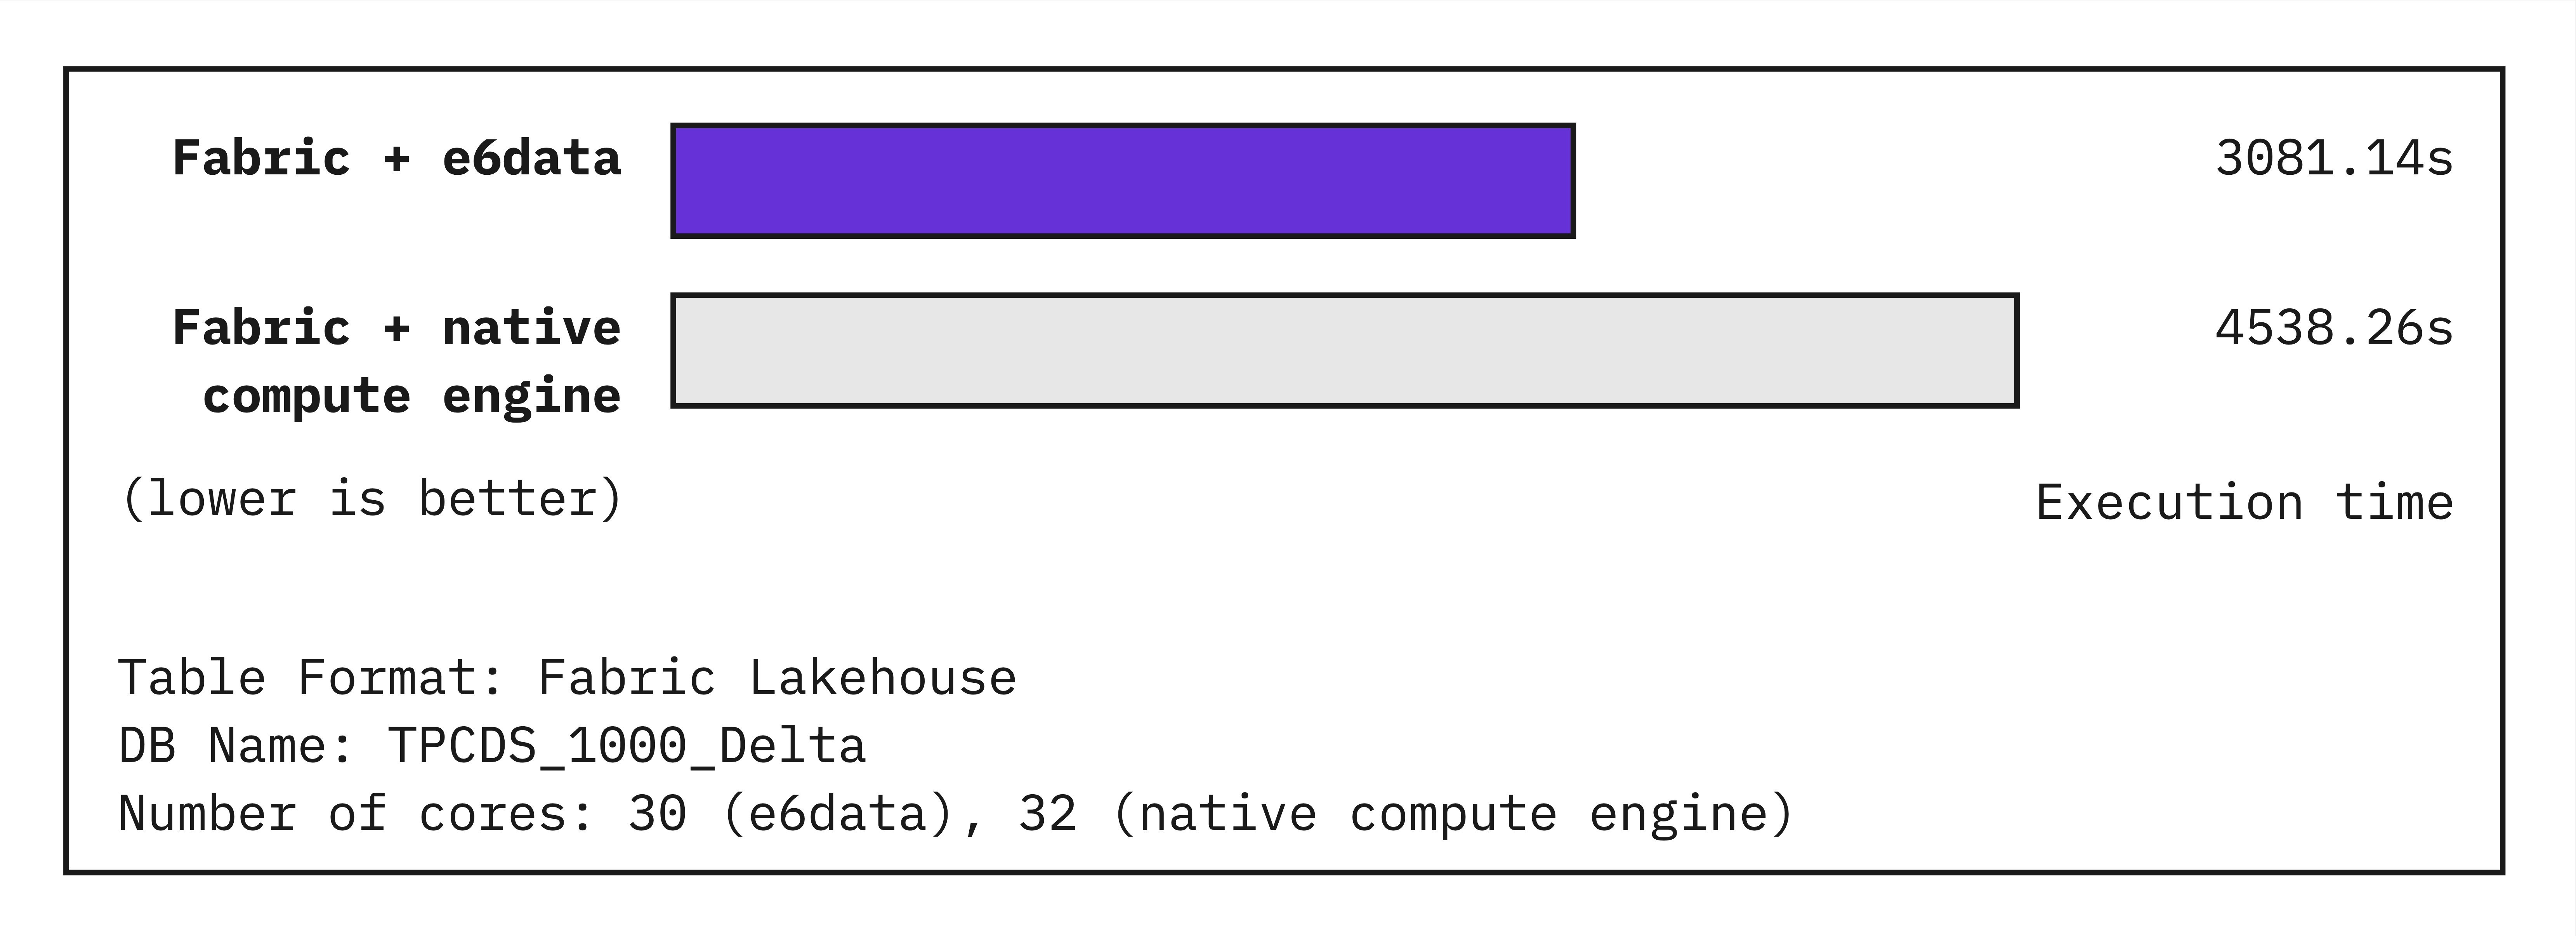
e6data for MS Fabric: 33% Increase in Performance and Optimized Capacity
e6data integrates with Microsoft Fabric to make querying data about 33% faster (as per benchmark reports) — helping you speed up data analytics while cutting costs by 2-3x. It directly taps into your OneLake data without any data movement.
Engineering · Mar 27, 2025
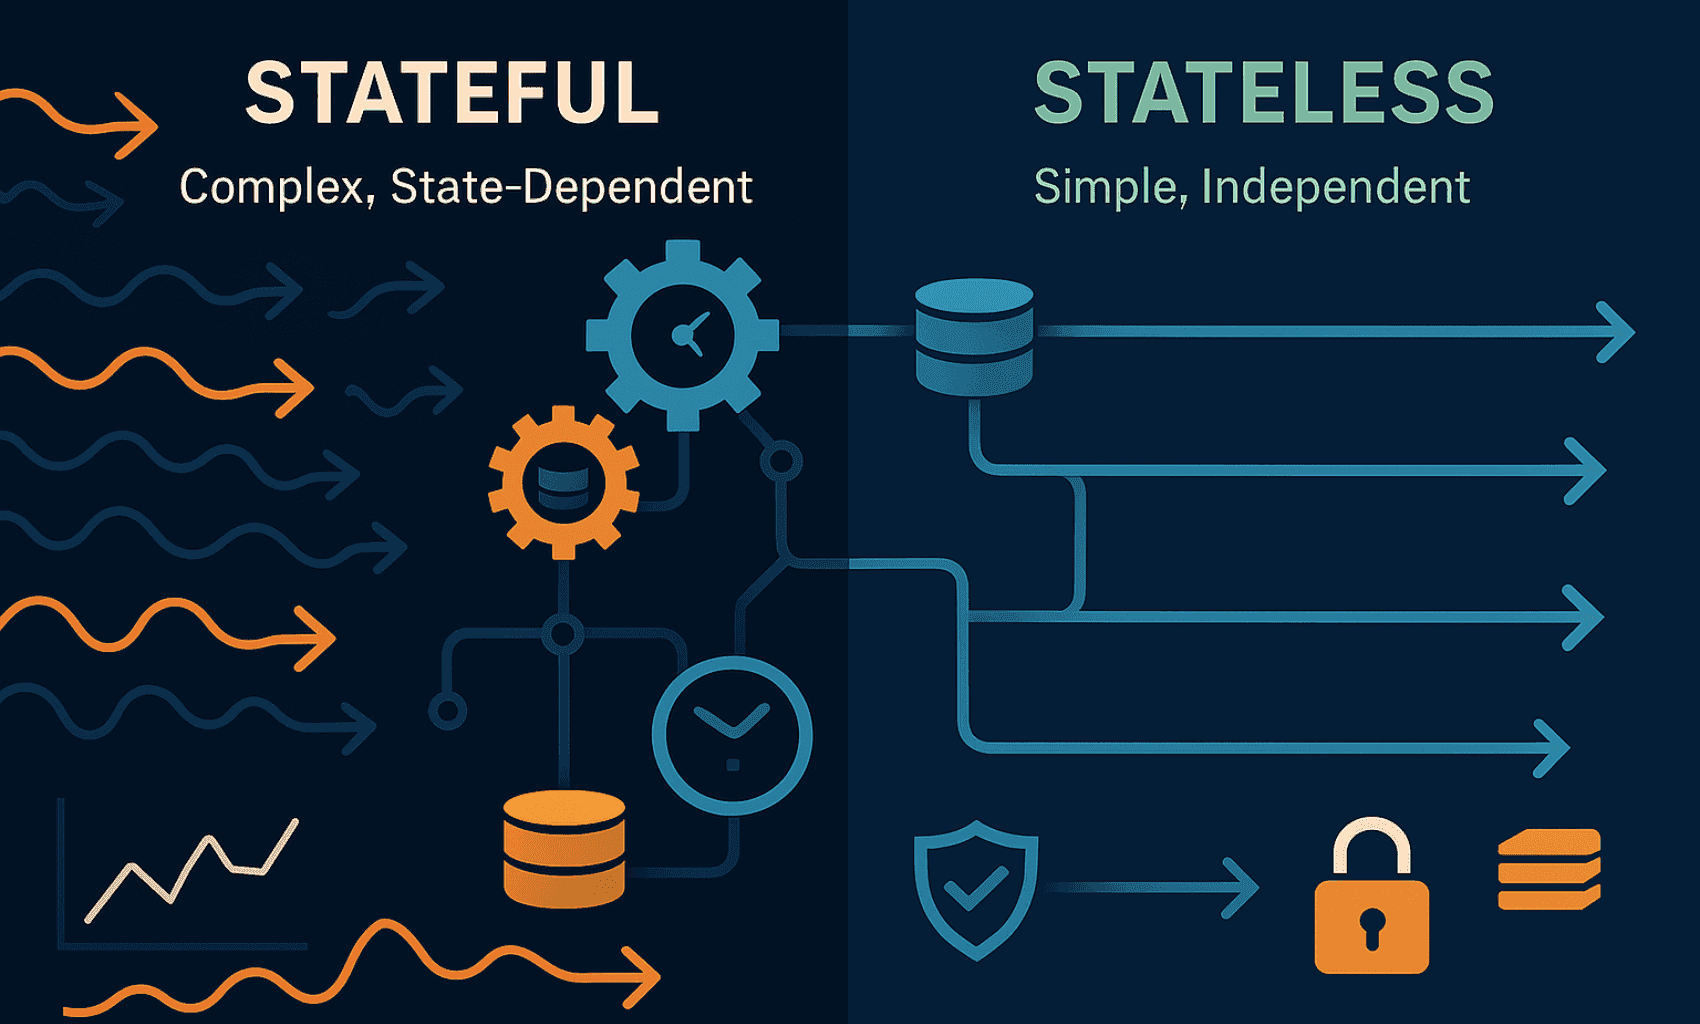
Stateful vs Stateless Stream Processing: Watermarks, Barriers, and Performance Trade-offs
Distributed stream processing fundamentally involves choosing between stateful stream processing —used extensively in event-time-based analytics and.
Engineering · Mar 19, 2025
Scaling Iceberg Writes with Confidence: A Conflict-Free Distributed Architecture for Fast, Concurrent, Consistent Append-Only Writes
Apache Iceberg is a cornerstone table format in modern data lakehouse systems. It is renowned for its ability to deliver transactional consistency, schema.
Engineering · Mar 17, 2025
Snappy Vs. ZSTD in Apache Iceberg: A Debate on Fast Writes Amid Small-File Challenges
Choosing the correct compression codec is crucial when optimizing Apache Iceberg tables for fast writes and reads. Iceberg often ends up writing many.
Privacy · Mar 11, 2025
e6data Achieves SOC 2, HIPAA, GDPR, and ISO 27001, Reinforcing Its Enterprise-grade Security and Zero-Migration Architecture
e6data , a lakehouse compute engine, today announced the successful completion of key enterprise compliance certifications, including SOC 2, HIPAA, GDPR.
Engineering · Jan 3, 2025
Under the Hood of Apache Iceberg: An Inside Look at the Metadata Evolution After Compaction
In traditional data warehouses, storage and computing are tightly integrated. By contrast, lakehouses–built with the Apache Iceberg format and Delta.
Engineering · Dec 26, 2024
From Hidden to Hero: Low-Level Technical Metadata Catalogs’ Relevance for the Future of Lakehouses
In the traditional world of data warehousing, metadata catalogs quietly operated behind the scenes. They were simple data dictionaries within a monolithic.
Engineering · Nov 27, 2024
Enhancing Query Performance in the Apache Iceberg: A Hands-On Guide to Sorting Within Partitions
Apache Iceberg is a high-performance, open-table format designed to manage large-scale analytic datasets with reliability and efficiency. It enables.
Engineering · Nov 22, 2024
The Ultimate Resource Hub for Optimizing Iceberg Tables
At e6data, we are big admirers of Apache Iceberg. We're witnessing a steep increase in its adoption, with our customers running E6data's query engine for.
Engineering · Nov 15, 2024
A Hands-On Guide to Snapshots and Time Travel in Apache Iceberg
Apache Iceberg is an open table format designed for managing petabyte-scale analytic datasets, providing a high-performance solution for modern data.
Engineering · Nov 12, 2024
The Lakehouse Evolution: Making Object Storage the Backbone of Modern Analytics
Lakehouse, or what is often called an open table format like Apache Iceberg, is a specification that helps achieve two key things: 1. Representing a table.
Engineering · Nov 7, 2024
A Comprehensive Guide for Managing Permissions in Hive Metastore for Lakehouses
Organizations are increasingly adopting lakehouse architectures to unify data warehouses and data lakes in today’s data-driven world. The Hive Metastore.
Engineering · Nov 5, 2024
The Shuffle Series: Part 1: Understanding the Shuffle Problem in Distributed Computing
Introduction Efficiently processing large datasets is essential and challenging in big data and distributed computing. At E6data, we've encountered many.